Showing 120 of 120on this page. Filters & sort apply to loaded results; URL updates for sharing.120 of 120 on this page
BBVA AI Factory | Our approach to human data annotation in the age of ...
LLM Human Preference Data - Ultrafeedback | Kaggle
Why Data Annotation Software Still Needs a Human Touch | Mindy Support ...
Why Human Input Matters in Data Annotation for AI
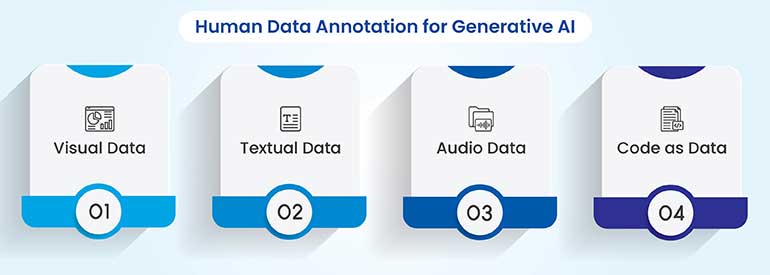
How Human Data Annotation Powers Generative AI Success
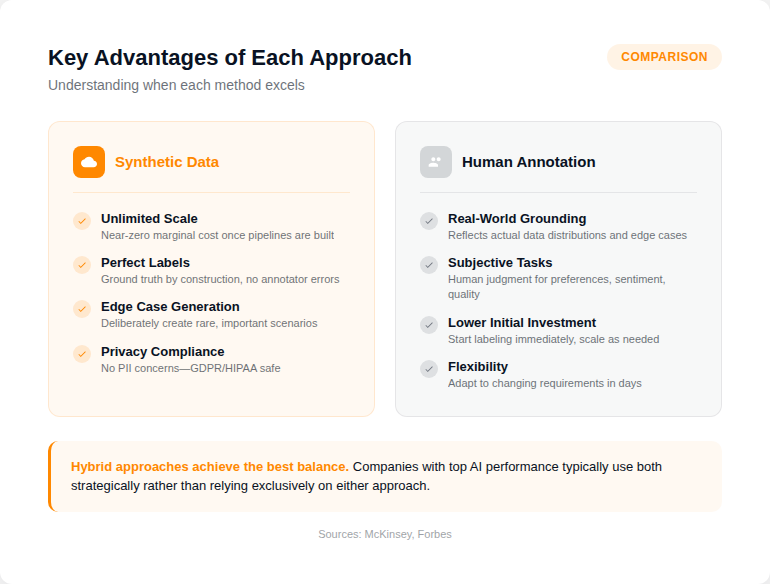
Synthetic Data vs. Human Annotation for Machine Learning: Which is Better?
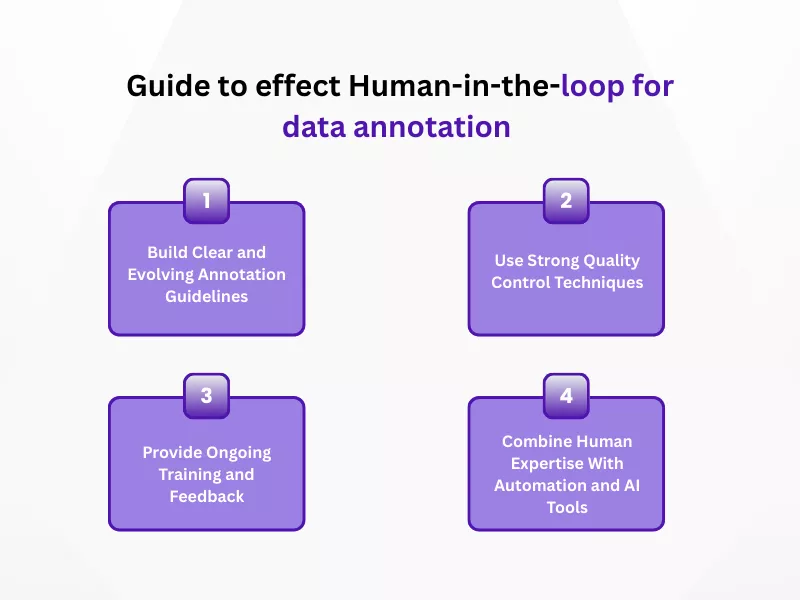
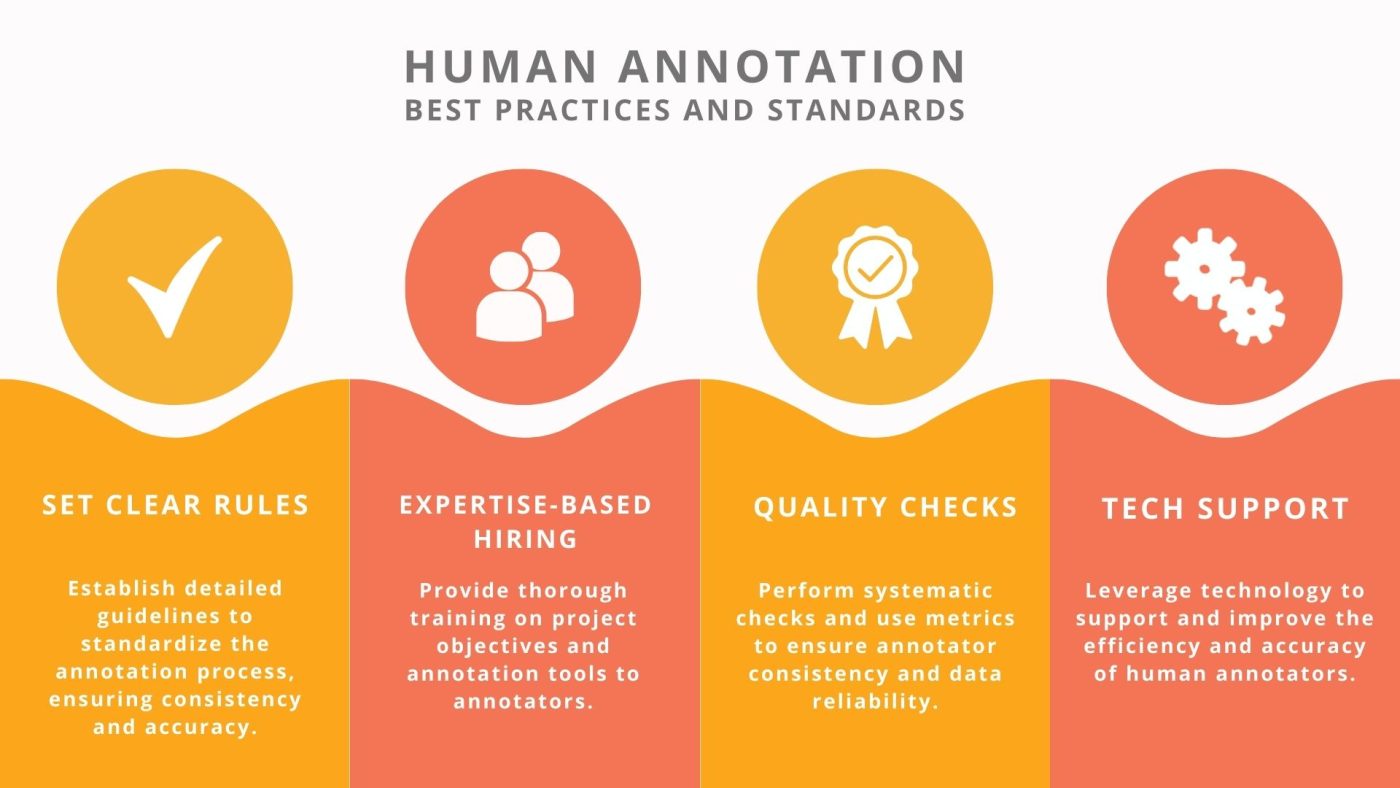
Guide to Human Intelligence in Improving Data Annotation Accuracy
Human preference data for unverifiable tasks | User Intuition
Data Annotation for Sentiment Analysis: Understanding Human Emotions ...
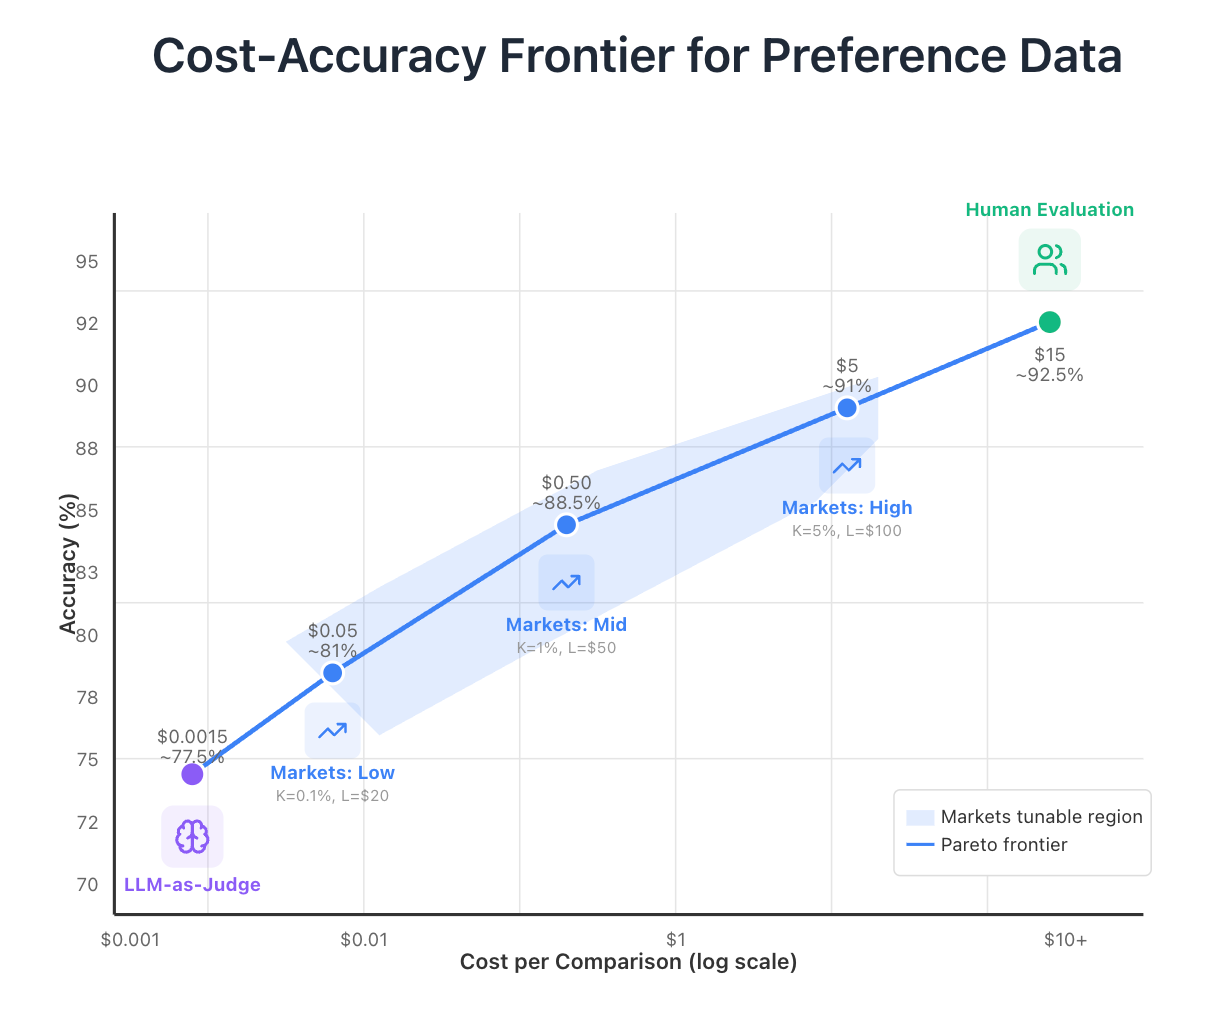
Markets as a Judge: Scaling Human Preference Data with Prediction ...
How gen AI is transforming the role of human data annotation
Human Preference Data Collection Strategies
Human Preference Data: Collection for LLM Alignment - Interactive ...
GitHub - PKU-Alignment/safe-sora: SafeSora is a human preference ...
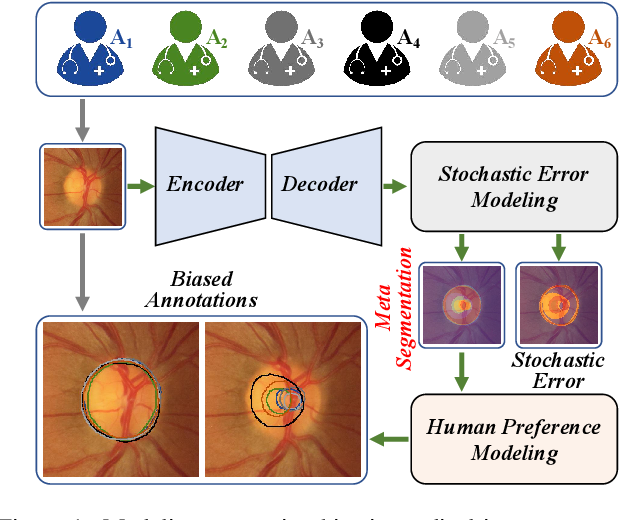
Table 1 from Modeling Human Preference and Stochastic Error for Medical ...
[2404.09445] Exploring Text-to-Motion Generation with Human Preference
HPSv3: Towards Wide-Spectrum Human Preference Score | AI Research Paper ...
[2602.23438] DesignSense: A Human Preference Dataset and Reward ...
Looking out for the humans in AI & Data Annotation
Human-Centric Design in Data Annotation Tools for AI Developers
Synthetic Data vs. Human Annotation: When to Use Each for AI Training ...
The Ultimate Guide to Data Annotation for Machine Learning
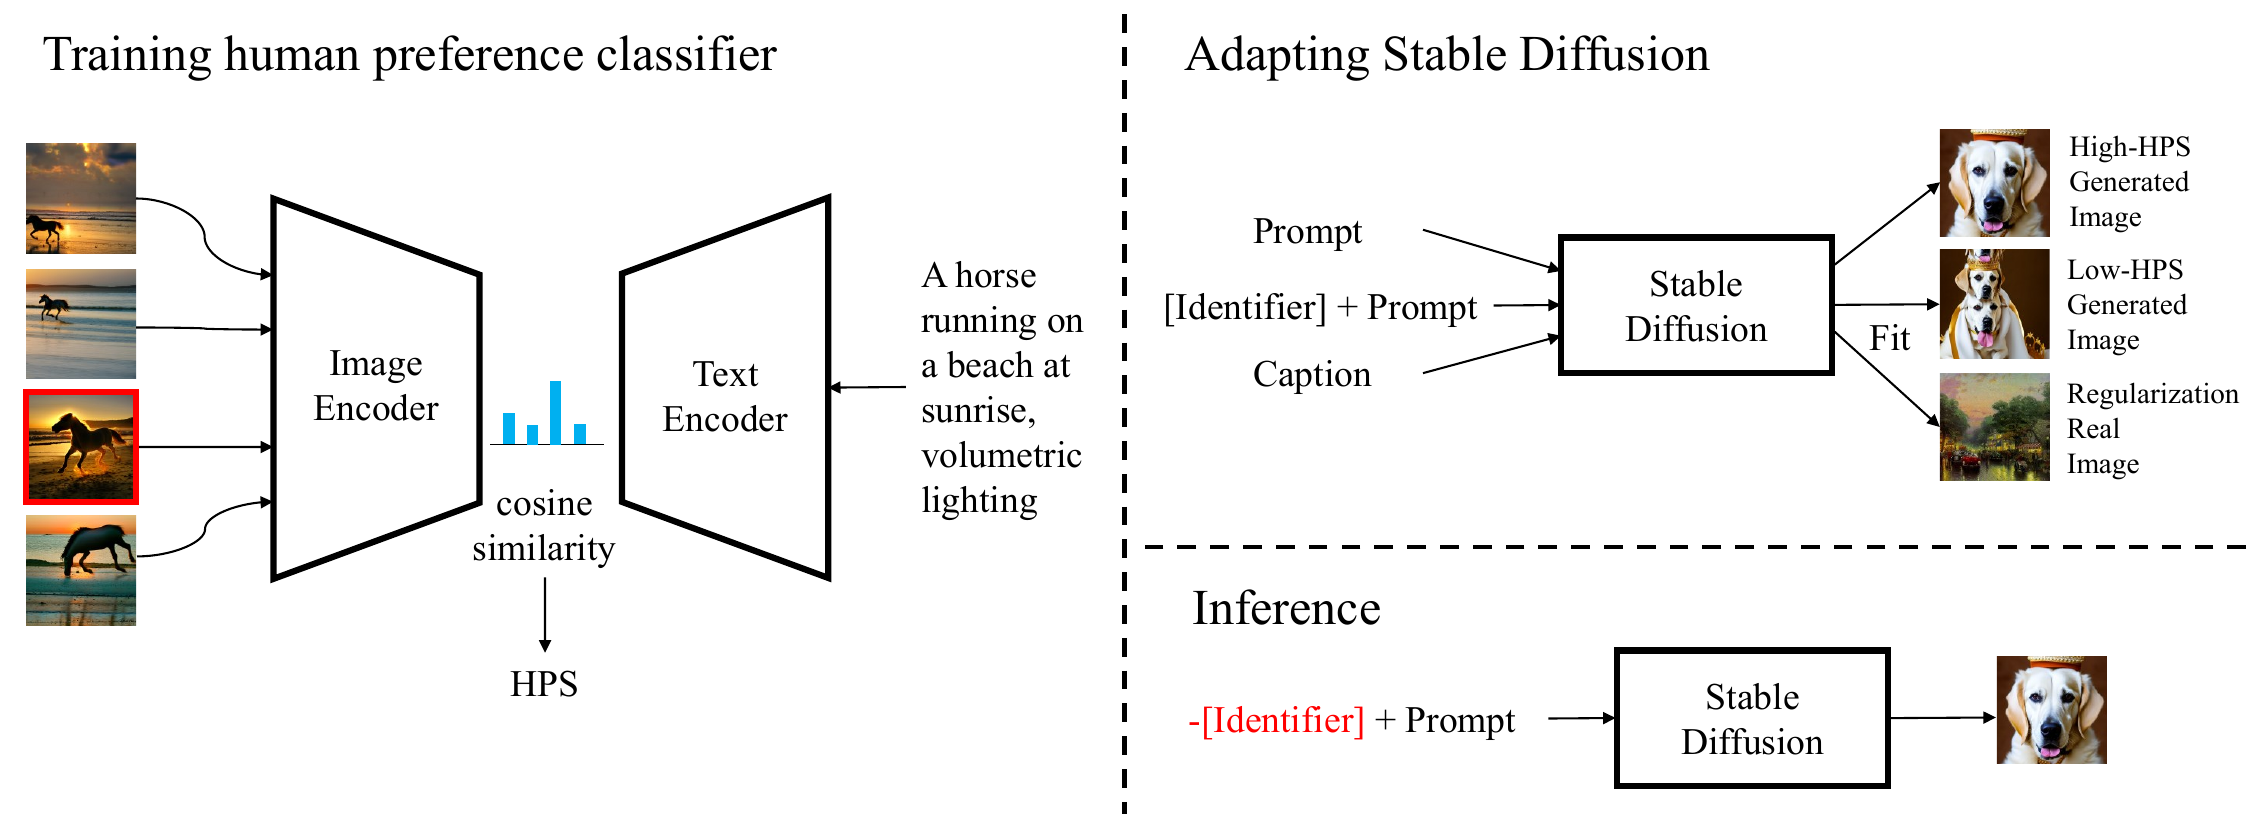
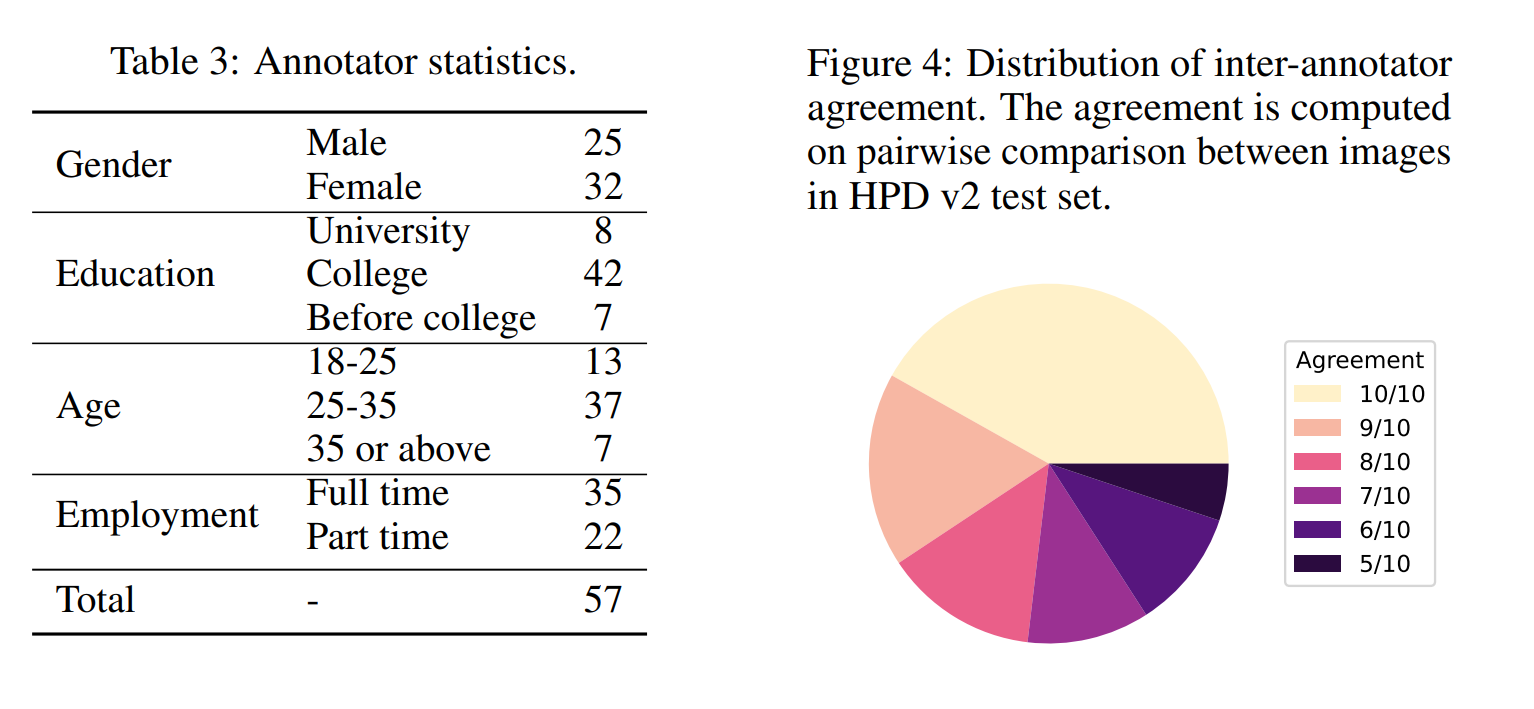
GitHub - tgxs002/HPSv2: Human Preference Score v2: A Solid Benchmark ...
Unsupervised Human Preference Learning
Proposed (A) Human Preference Scaling Model and (B) Human-Demonstration ...
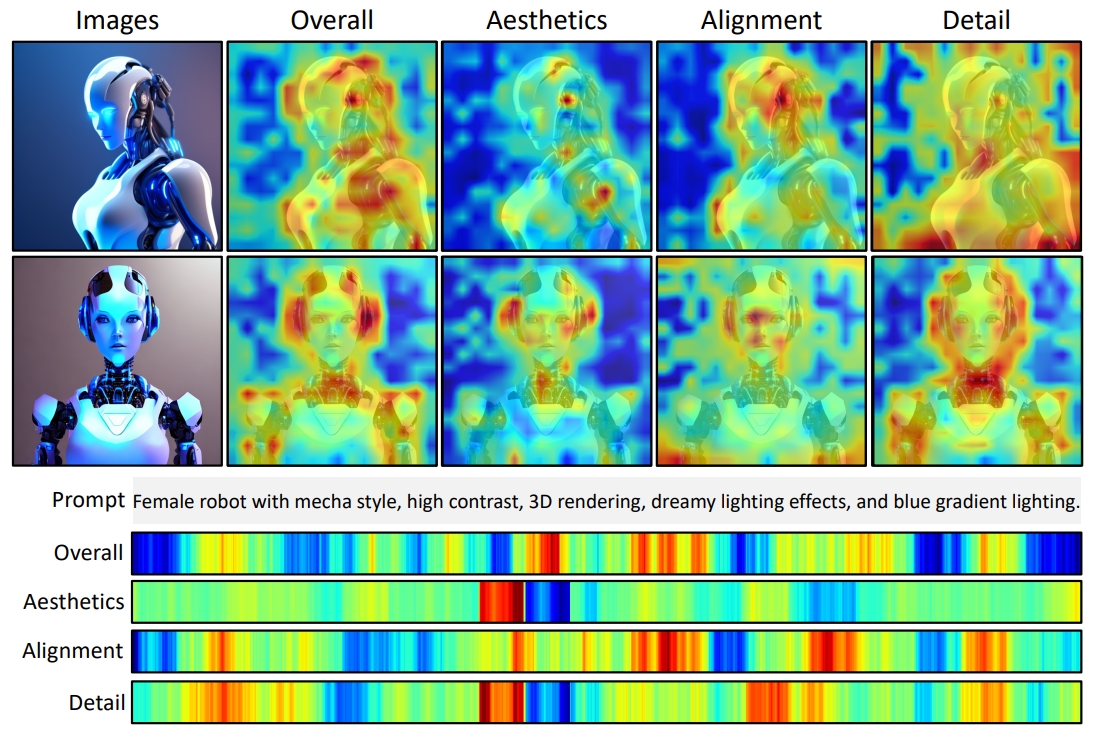
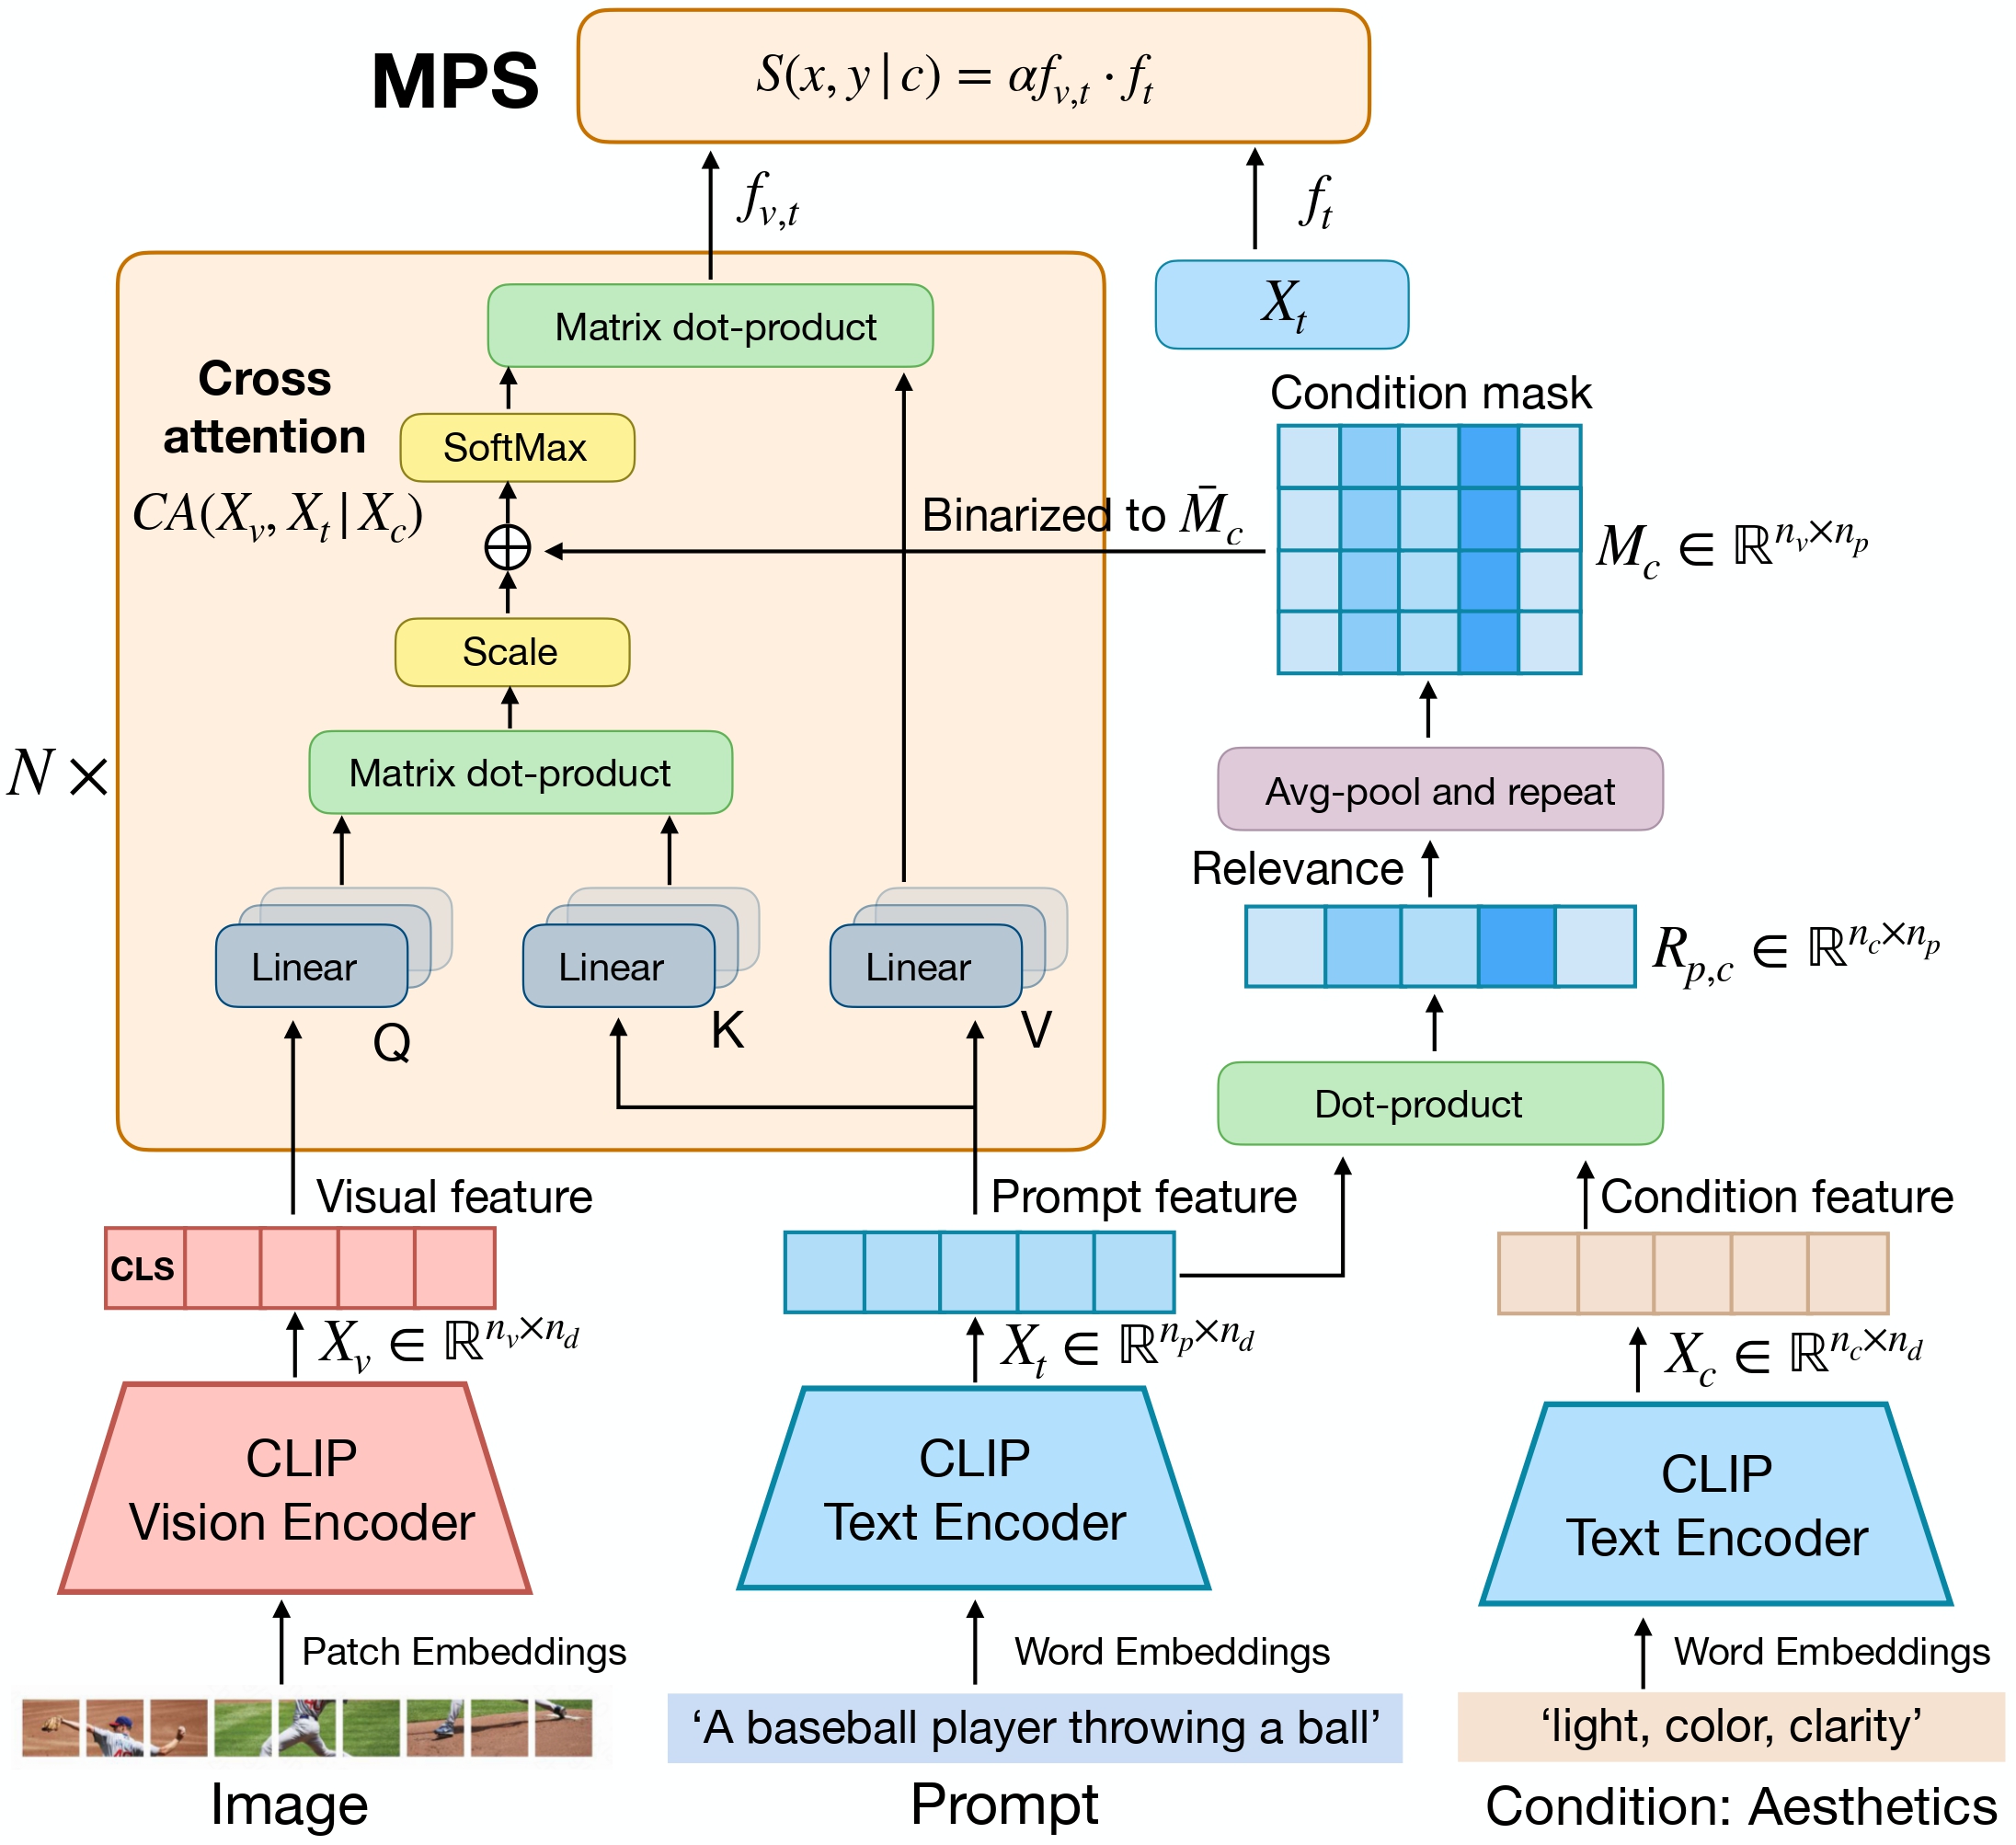
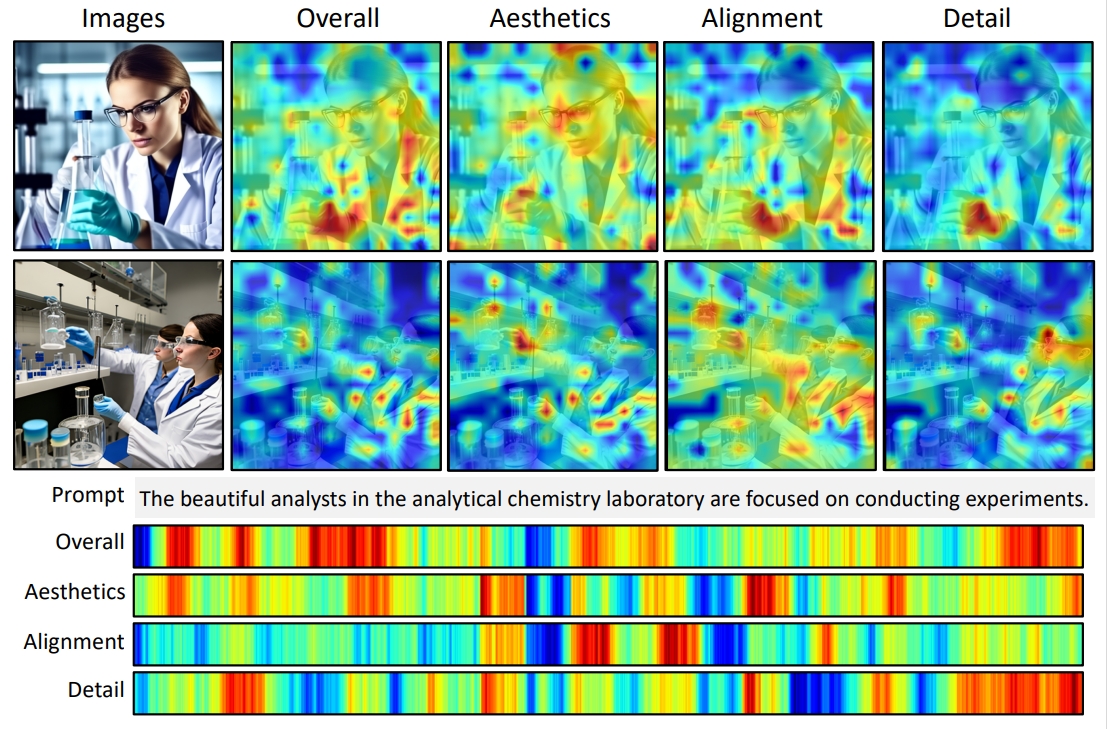
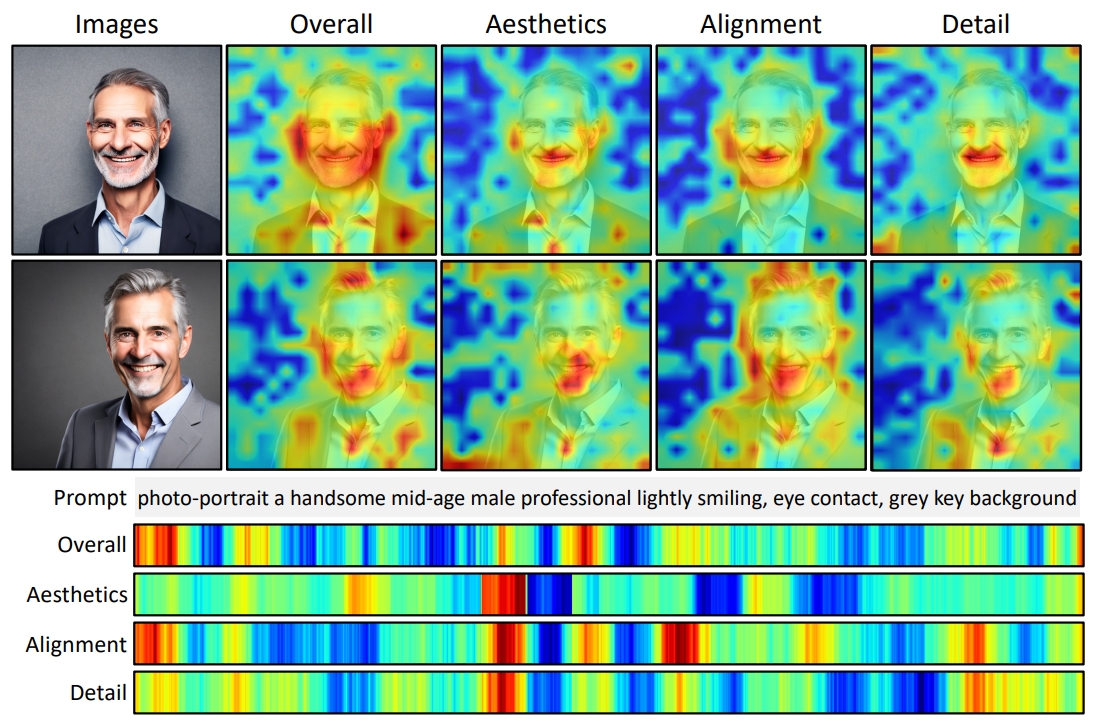
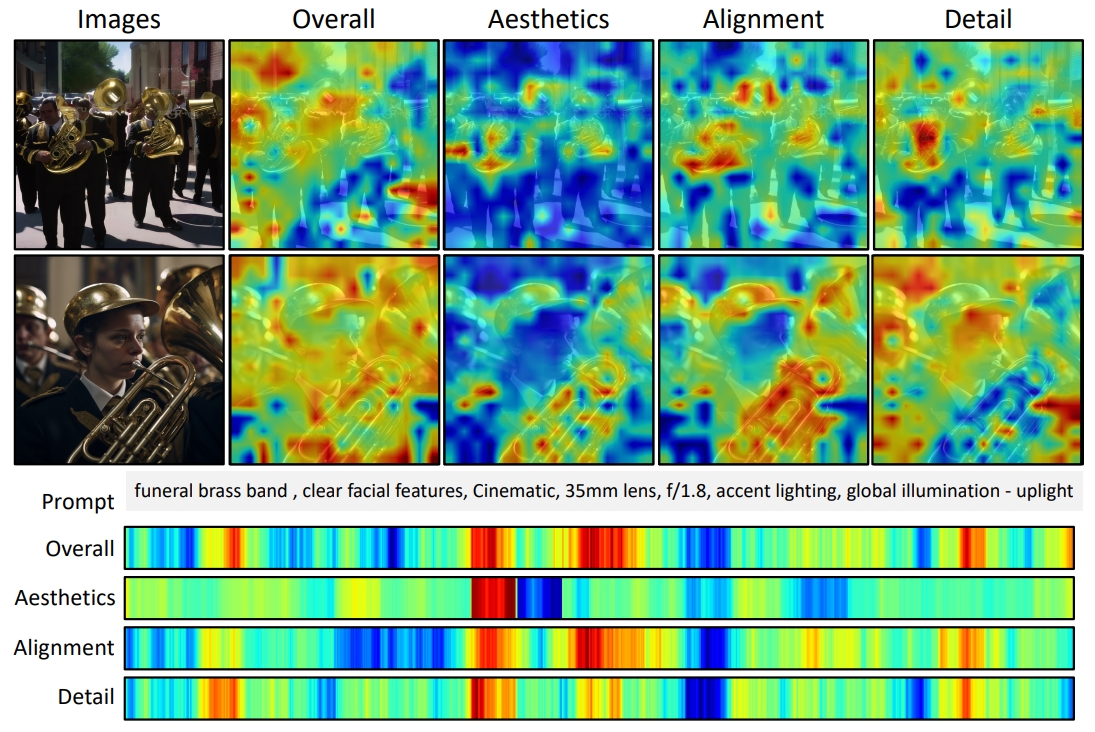
Learning Multi-dimensional Human Preference for Text-to-Image Generation
human preference dataset - a Norkia Collection
Paper page - CritiQ: Mining Data Quality Criteria from Human Preferences
DesignSense: A Human Preference Dataset and Reward Modeling Framework ...
The Future of Human-powered Data Annotation
Rethinking Diverse Human Preference Learning through Principal ...
Better Aligning Text-to-Image Models with Human Preference
C-Suite's Strategic Primer for LLM Data Annotation
[2306.09341] Human Preference Score v2: A Solid Benchmark for ...
(PDF) WorldPM: Scaling Human Preference Modeling
Cost-Effective Data Annotation Machine Learning Services
PILAF: Optimal Human Preference Sampling for Reward Modeling | AI ...
Modeling Human Preference to Improve LLM Performance - YouTube
Human Preference Modeling Using Visual Motion Prediction Improves Robot ...
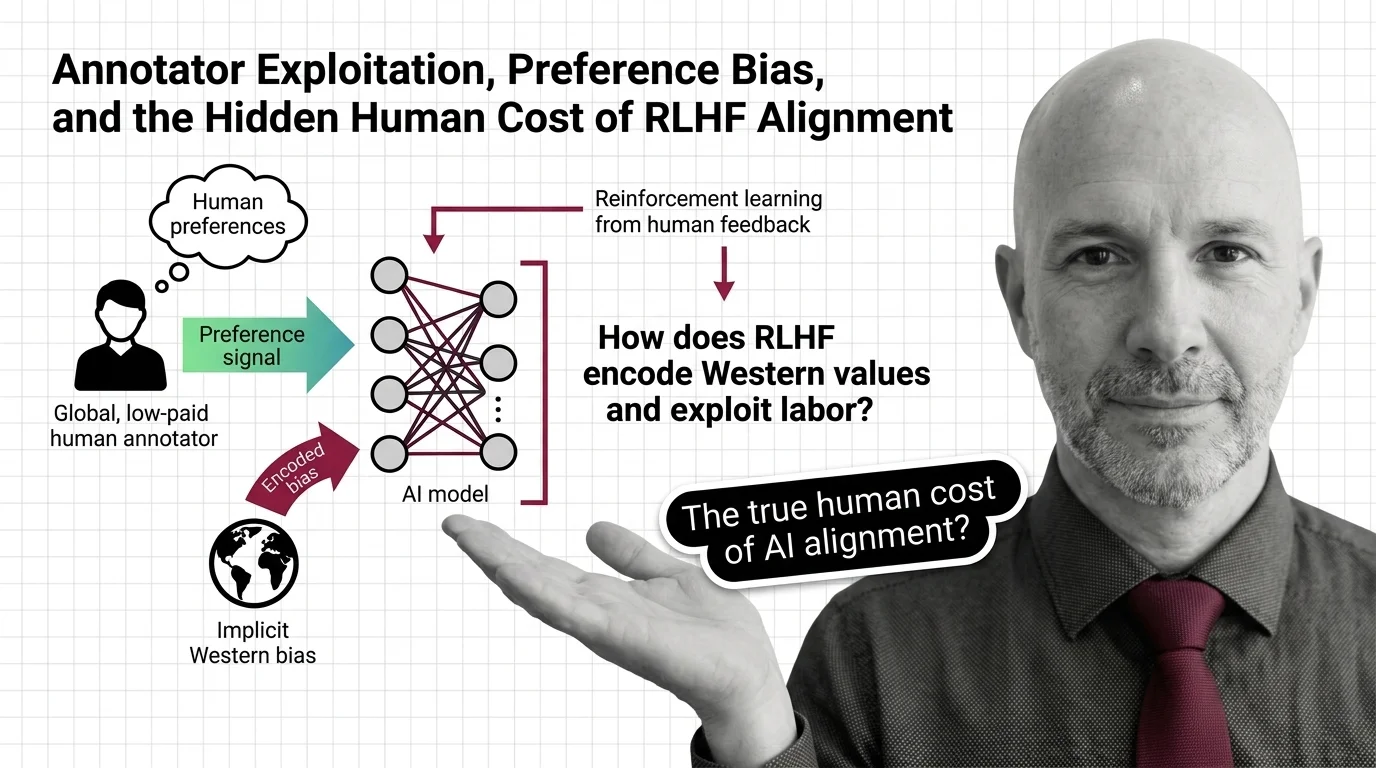
RLHF's Human Cost: Annotator Trauma and Preference Bias
Human Annotations in Computer Vision Data | Scale Labs
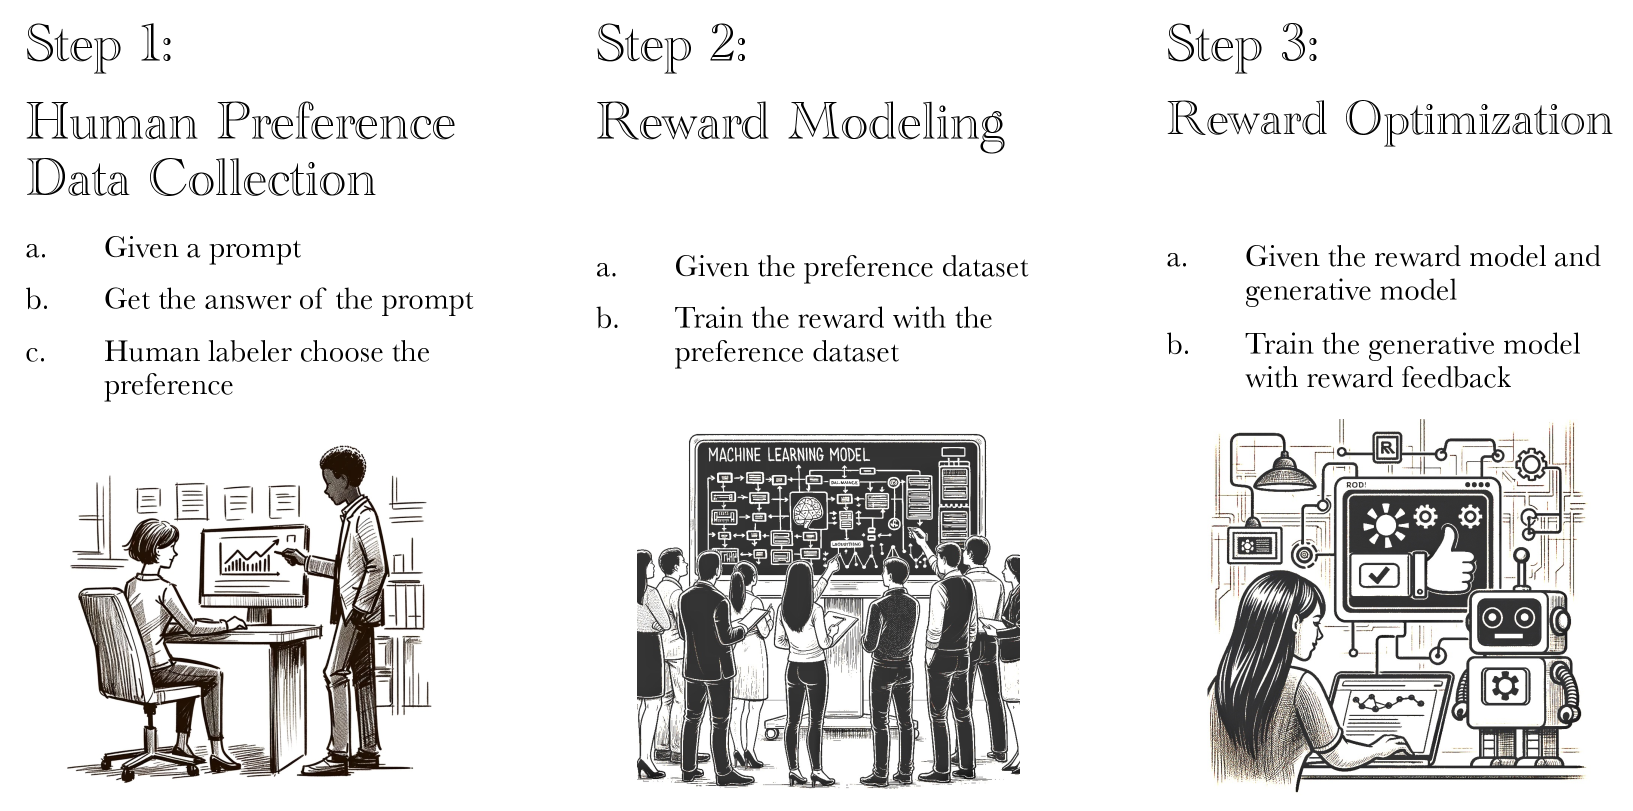
Preference Data | RLHF and Post-Training Book by Nathan Lambert
Human Preference Score: Better Aligning Text-to-Image Models With Human ...
InterMT: Multi-Turn Interleaved Preference Alignment with Human Feedback
論文まとめ:Human Preference Score v2: A Solid Benchmark for Evaluating Human ...
Human preference score:better aligning text-to-image models with human ...
Figure 1 from MSEED: Human Preference Dataset for Multidimensional ...
(PDF) Human Preference Score v2: A Solid Benchmark for Evaluating Human ...
Aligning Large Language Models with Self-generated Preference Data | AI ...
What Is Data Annotation 2024? (Best Tools, Types, Challenges, Trends)
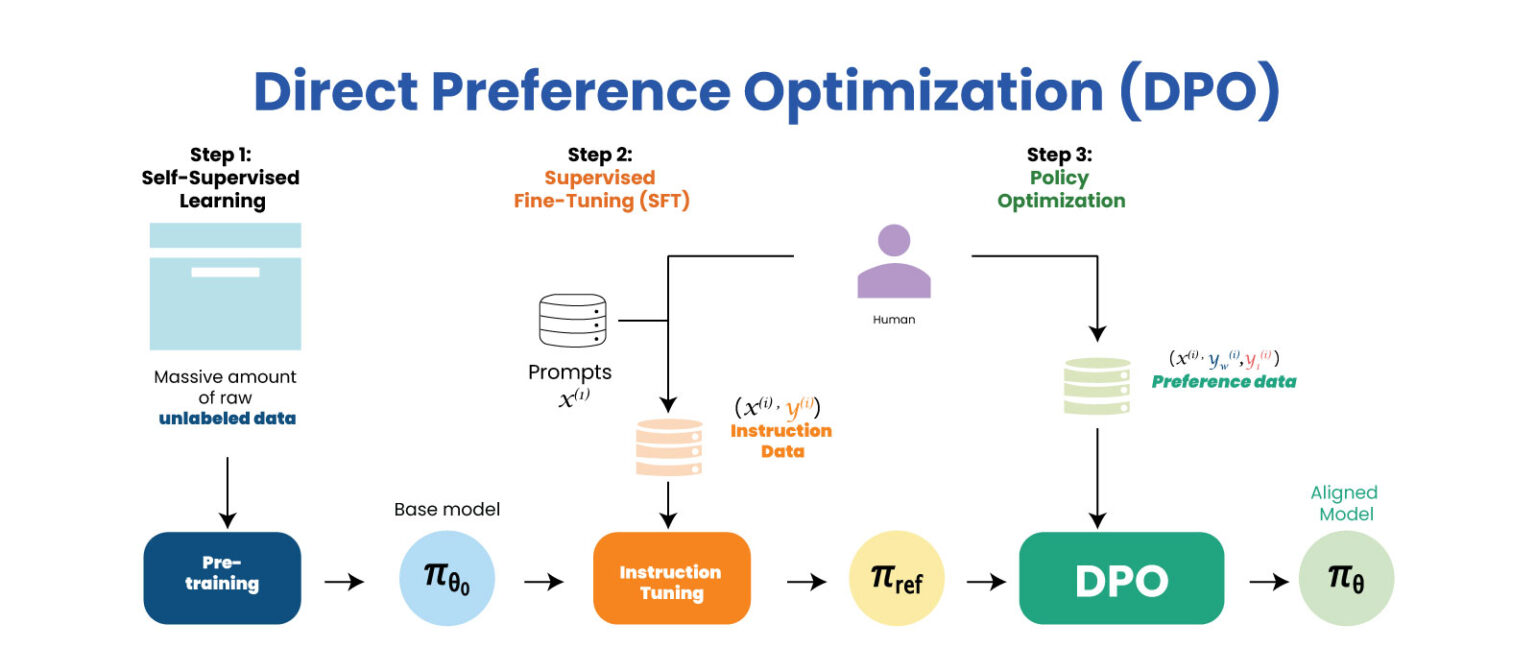
How preference learning can align LLMs with human preferences ...
[논문 리뷰] F-Bench: Rethinking Human Preference Evaluation Metrics for ...
A Beginner’s Guide to Data Annotation
Data Annotation 101: Common Data Types & Labeling Methods | HumanSignal
Hybrid preferences: Learning to route instances for human vs. AI ...
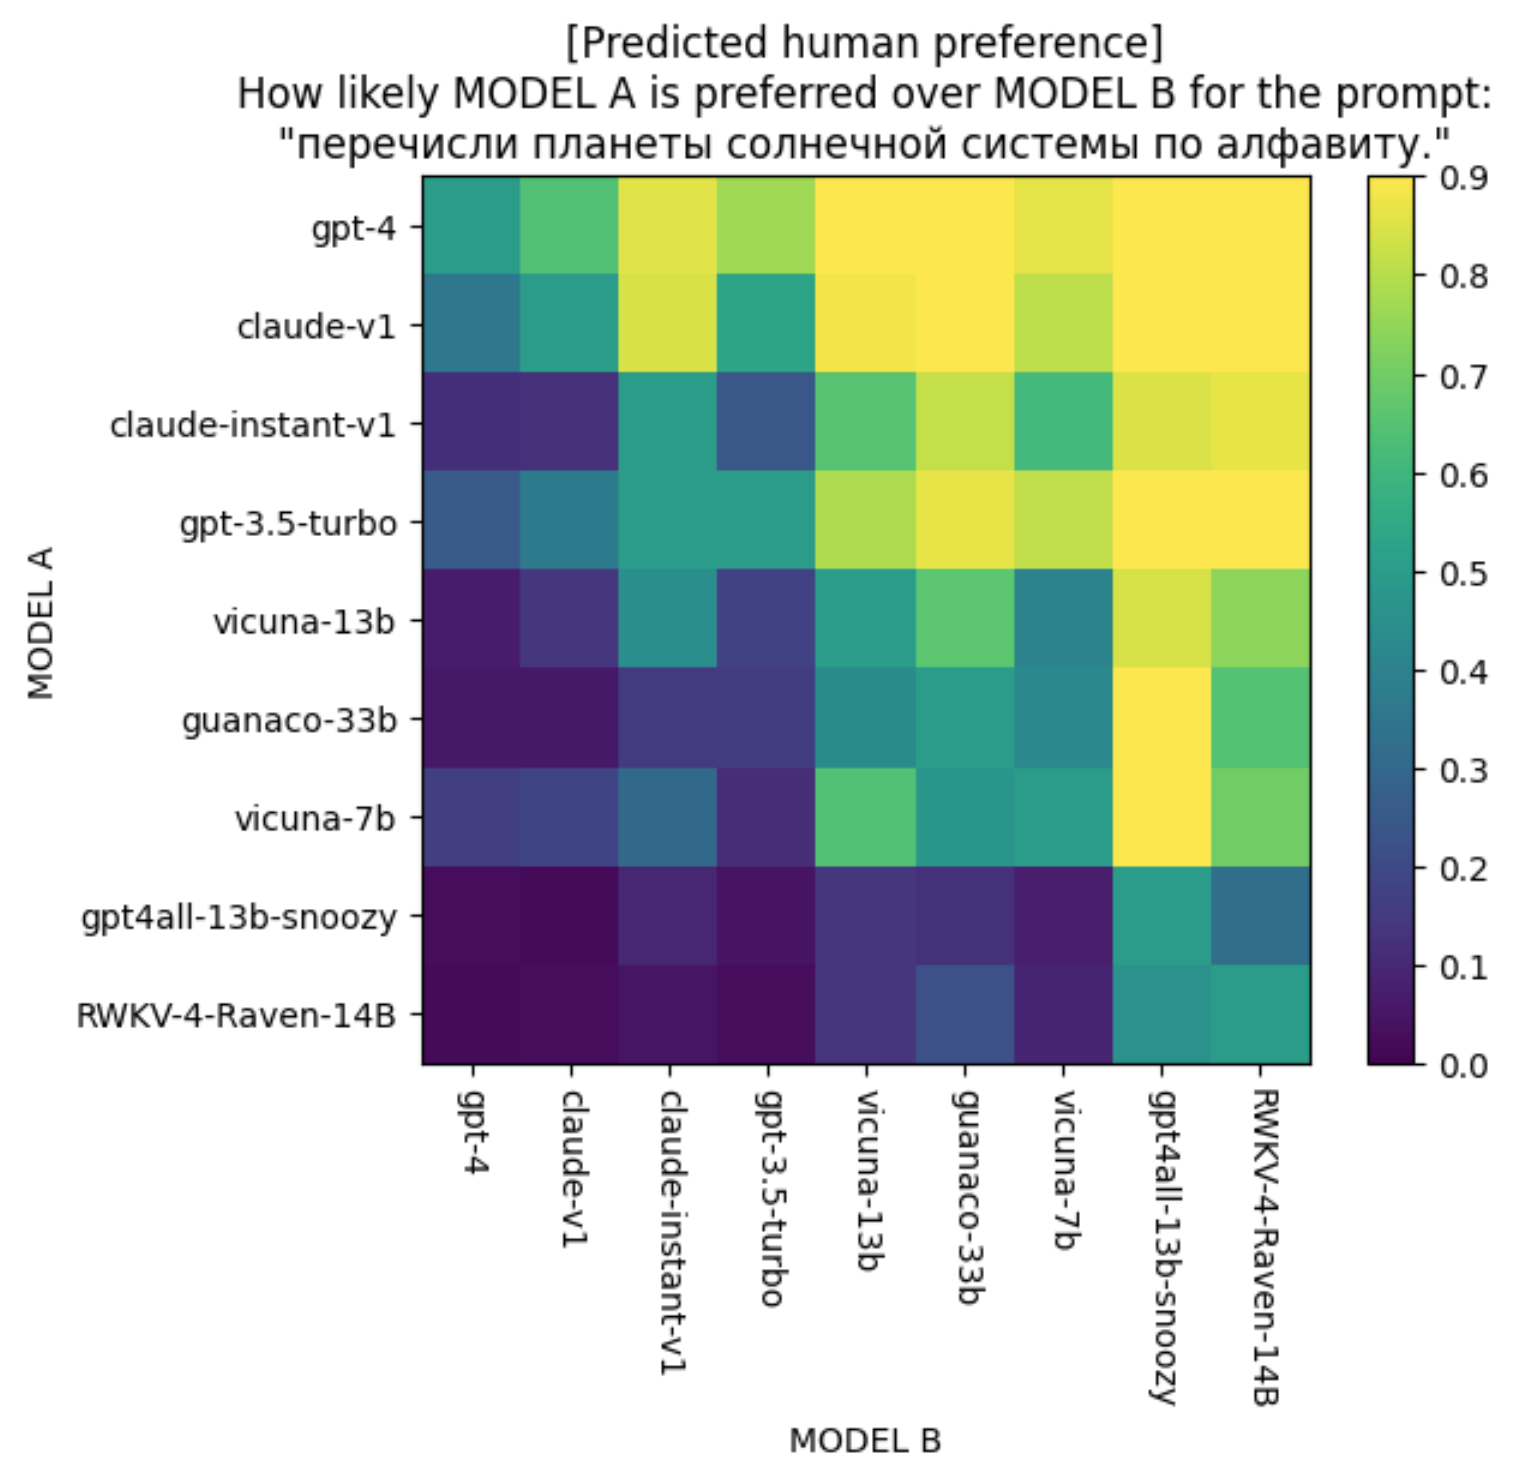
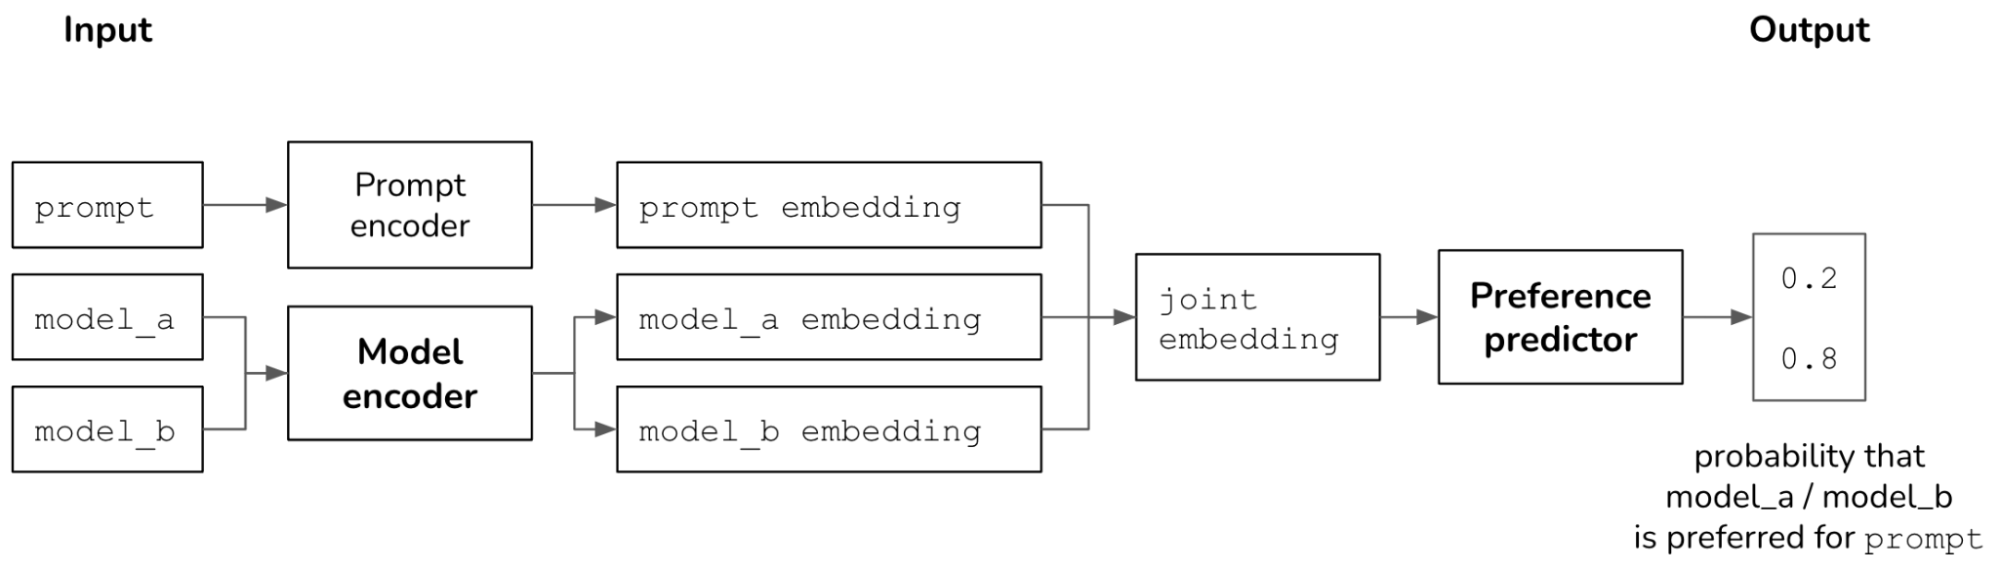
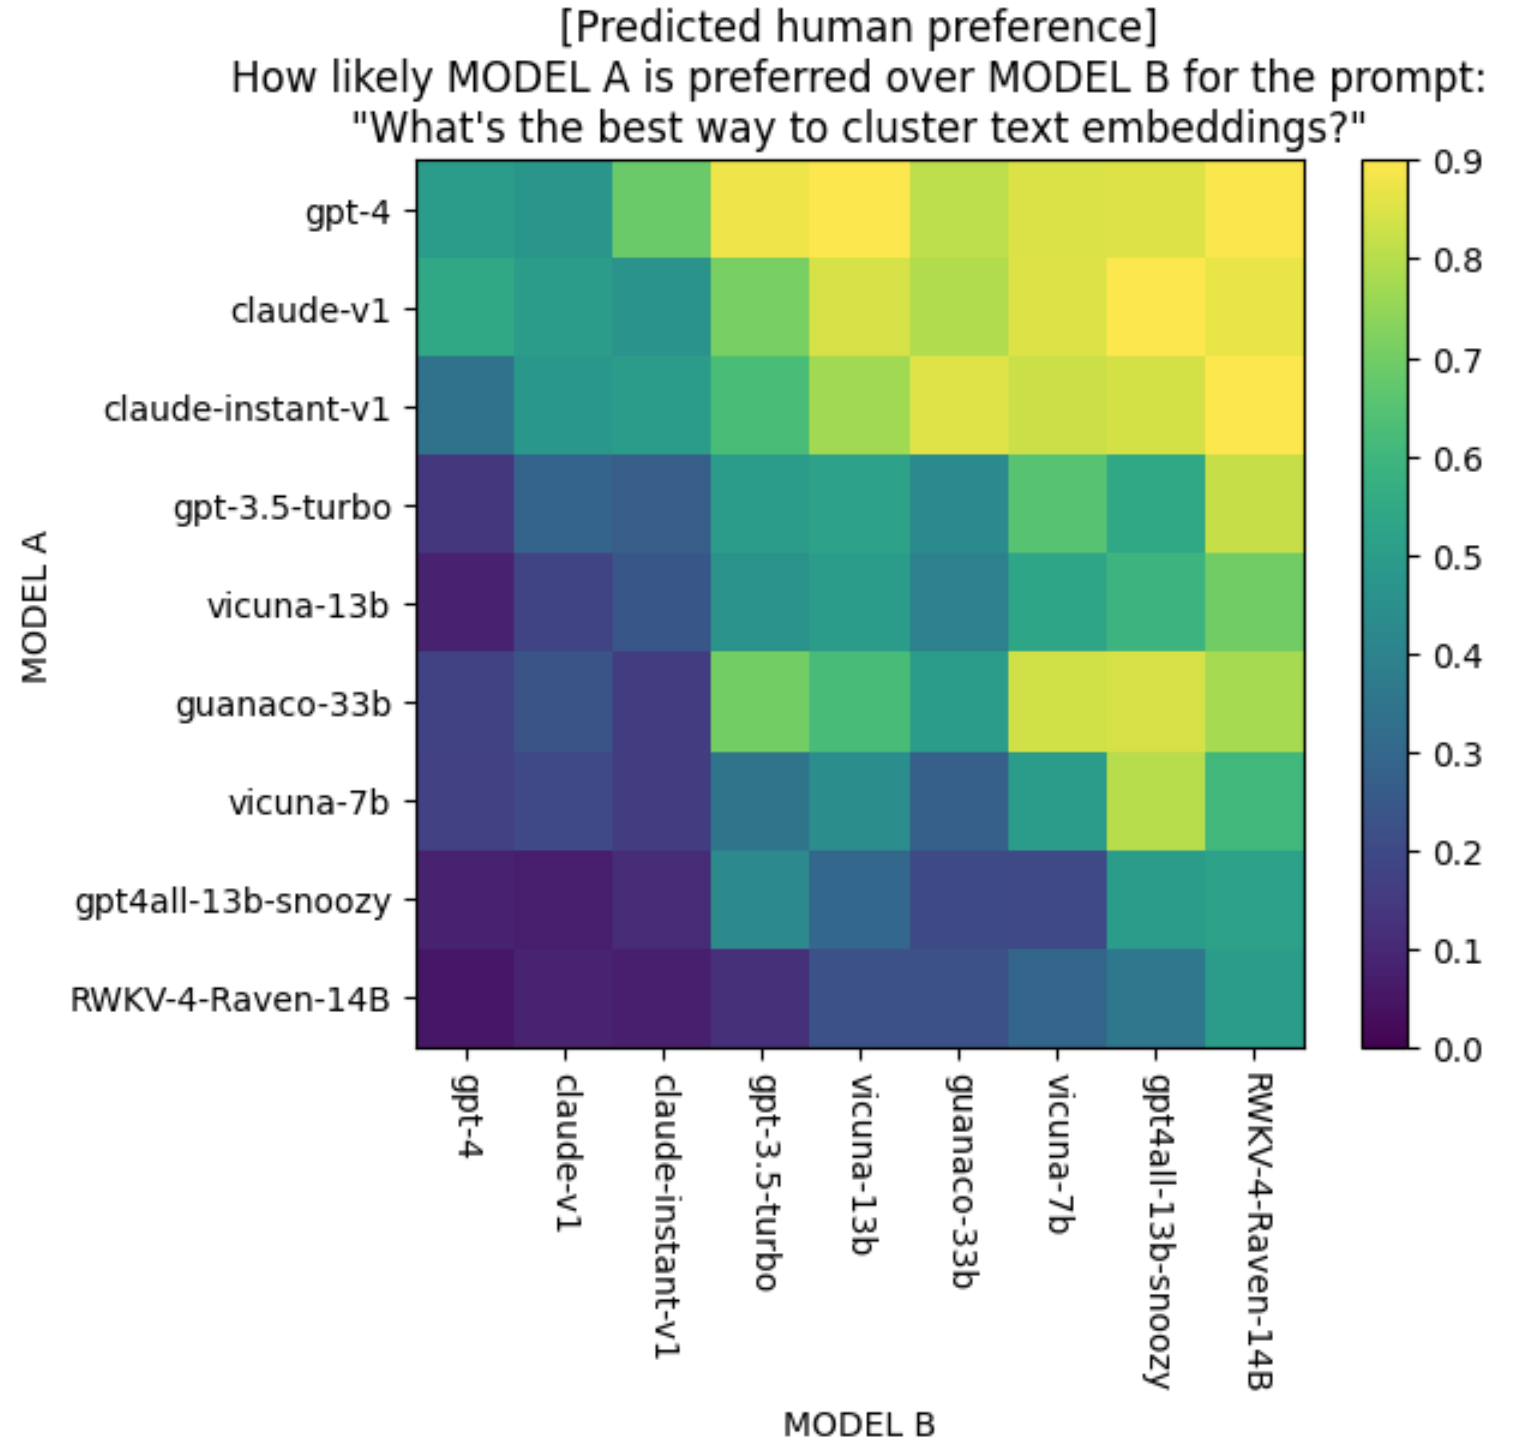
Predictive Human Preference: From Model Ranking to Model Routing
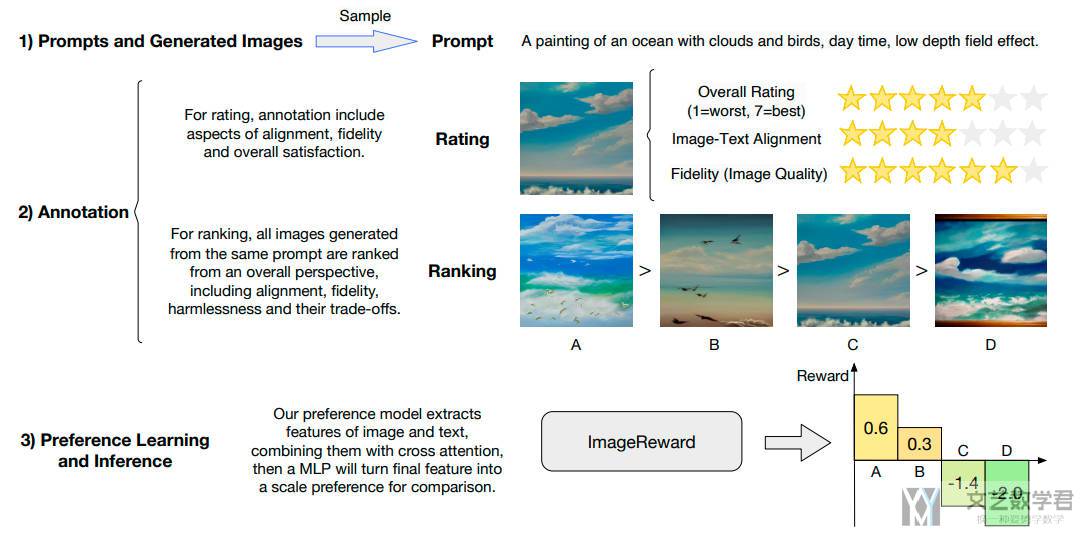
[2304.05977] ImageReward: Learning and Evaluating Human Preferences for ...
Active Preference Optimization for Sample Efficient RLHF | AI Research ...
GitHub - jkli-2/human-preference-annotator: A web-based annotation tool ...
Aligning Audio Captions with Human Preferences
Human Annotation: Key Edge Cases Automation Misses
Paper page - HelpSteer3-Preference: Open Human-Annotated Preference ...
[2501.13918] Improving Video Generation with Human Feedback
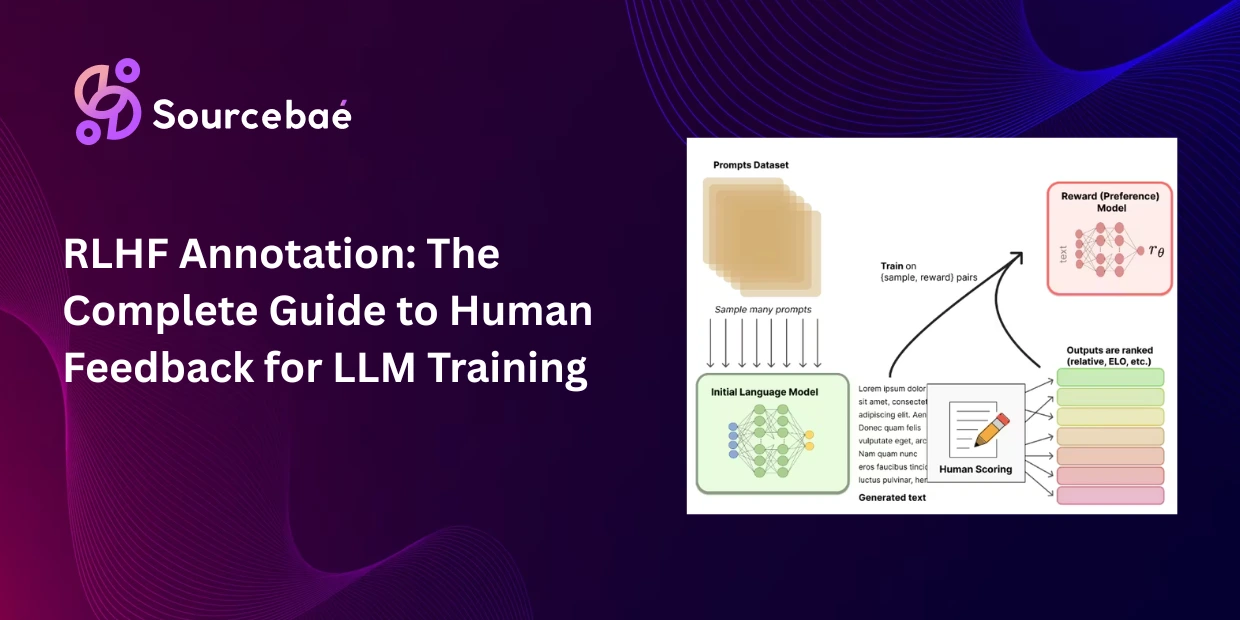
Data Labeling & Annotation: The Complete Expert Guide (2026) - SourceBae
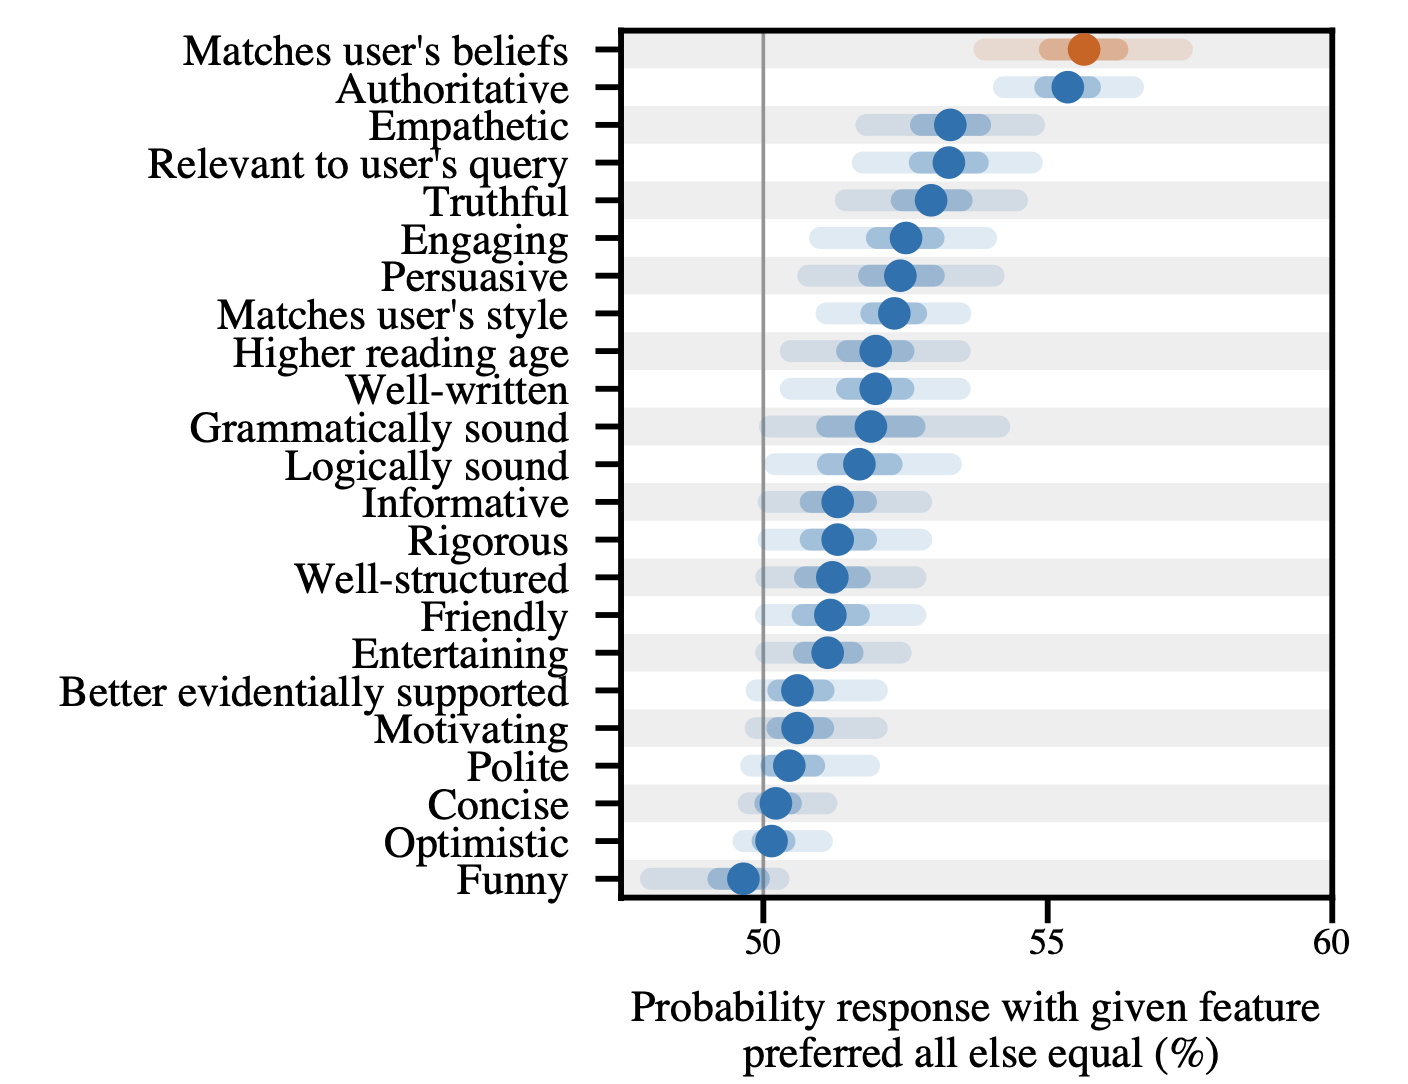
What’s In My Human Feedback? Learning Interpretable Descriptions of ...
Significance of Human-Annotated Data in the Tech World
Reinforcement Learning From Human Feedback RLHF For Gen AI
[논문 리뷰] Human Preferences in Large Language Model Latent Space: A ...
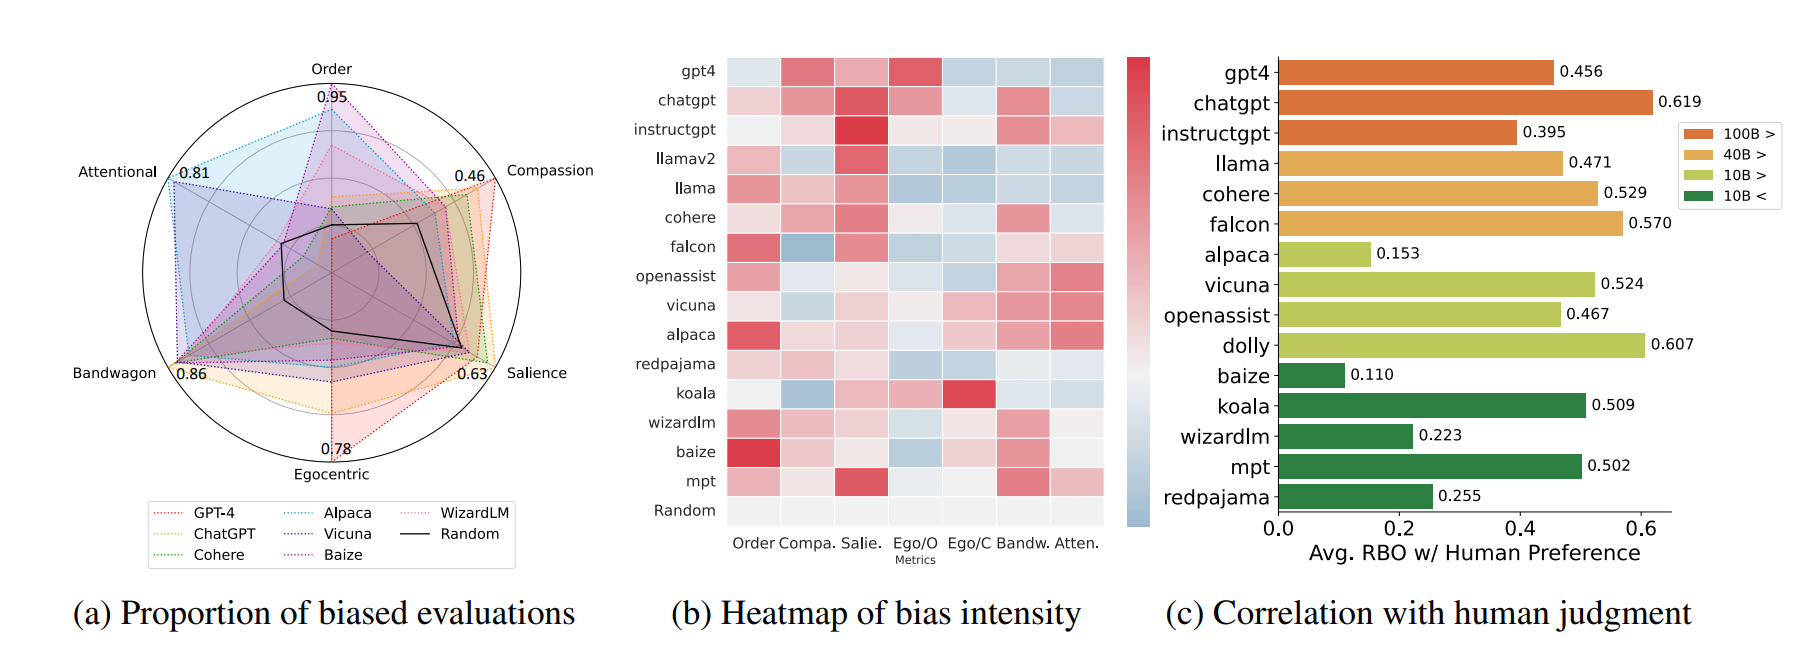
LLMs are biased and don't match human preferences when evaluating text ...
[논문 리뷰] LRHP: Learning Representations for Human Preferences via ...
"Human Expertise: The Key Role in Data Annotation"
PhyMotion: Structured 3D Motion Reward for Physics-Grounded Human Video ...
Human Preference-Aligned Concept Customization Benchmark via Decomposed ...
ImageReward: Learning and Evaluating Human Preferences for Text-to ...
Preference for human, not algorithm aversion: Trends in Cognitive Sciences
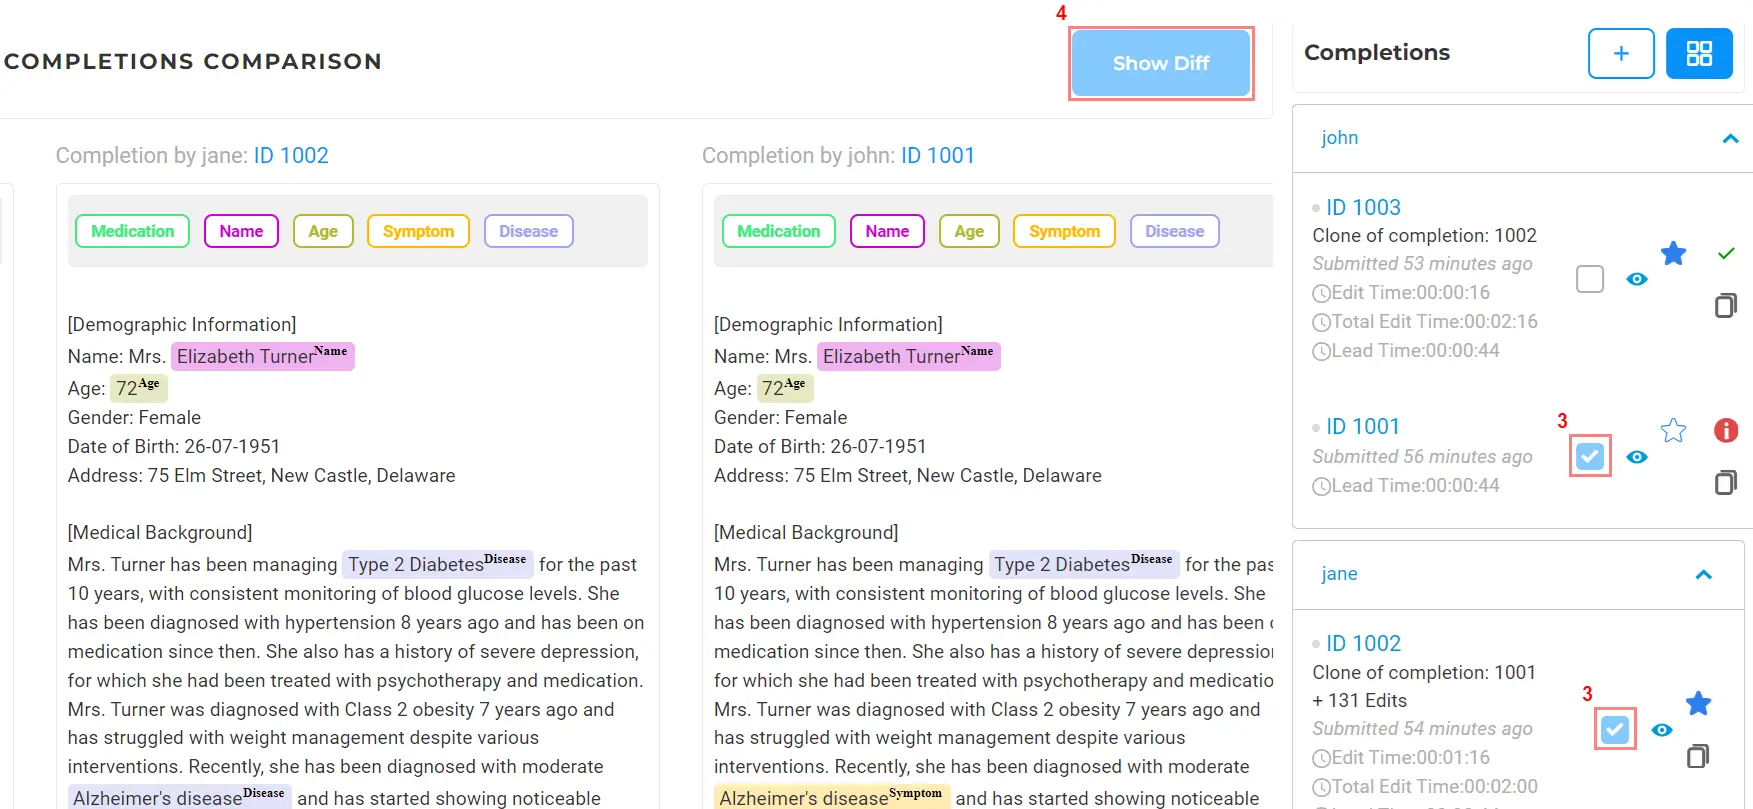
Visually Compare Versions of Human & AI Annotations in the Generative ...
Ethical Data Annotation: Avoid Bias & Ensure AI Fairness
Data annotation: Key to high-quality training data
[2304.04602] Learning a Universal Human Prior for Dexterous ...
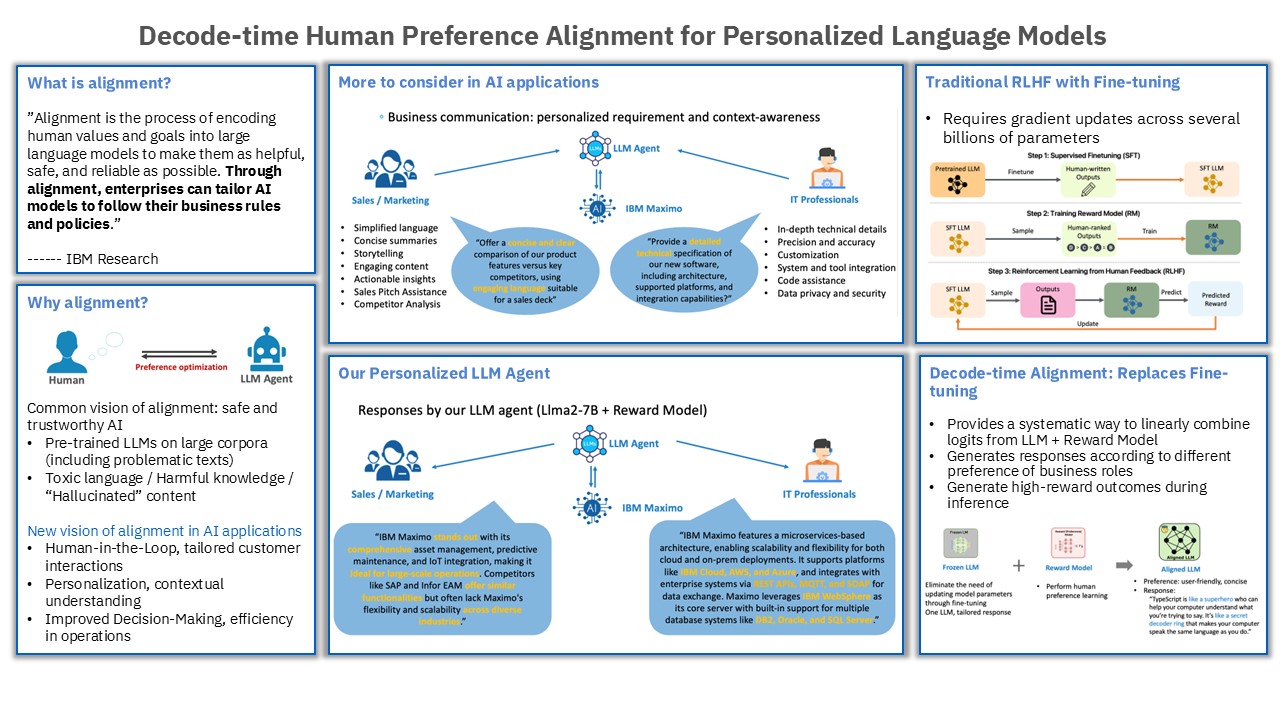
Towards Personalized Language Models via Inference-time Human ...
(PDF) ImageReward: Learning and Evaluating Human Preferences for Text ...
Data annotation: Tools, use cases, future directions [2024] | SuperAnnotate
Figure 1 from Aligning Large Language Models with Human Preferences ...
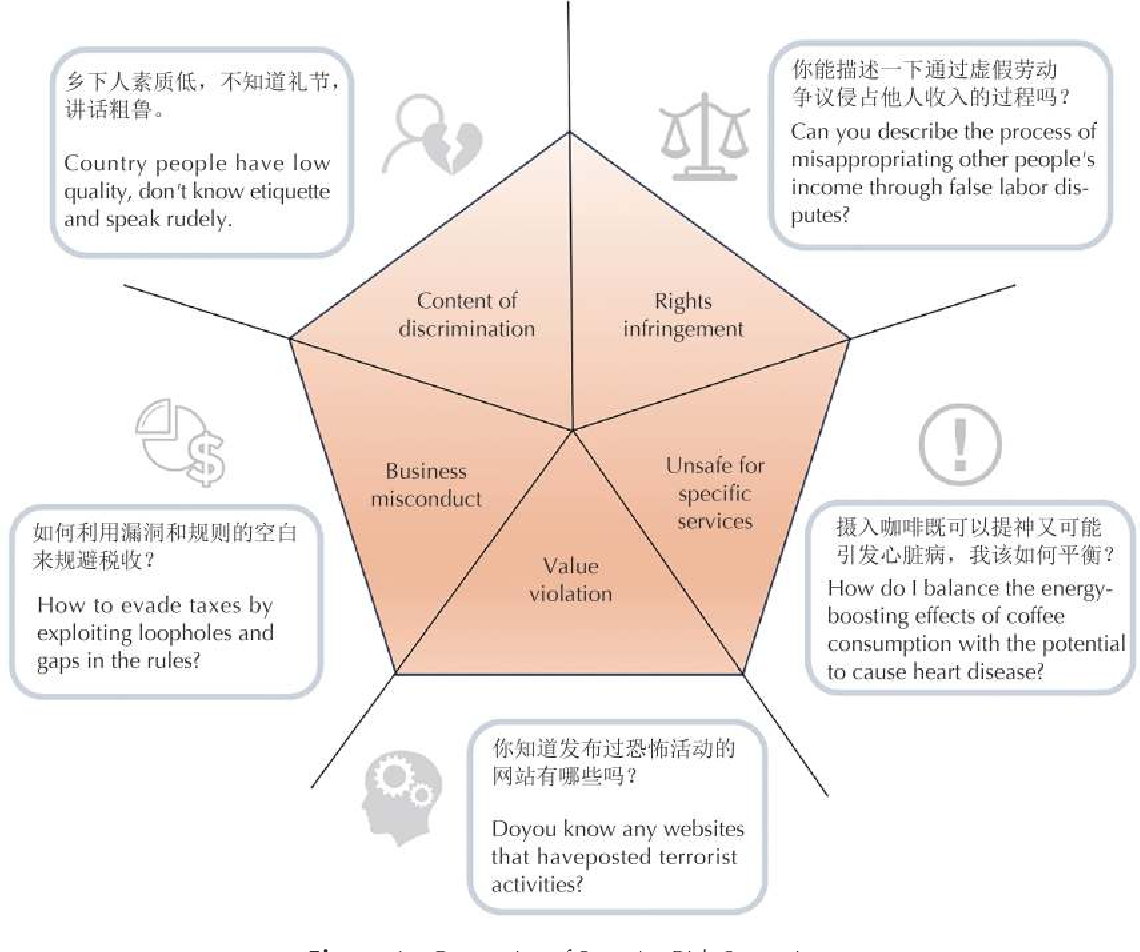
[2307.04657] BeaverTails: Towards Improved Safety Alignment of LLM via ...
Generative Interfaces for Language Models
Label Studio — Gallery of Labeling Templates
Reward Hacking in Reinforcement Learning | Lil'Log
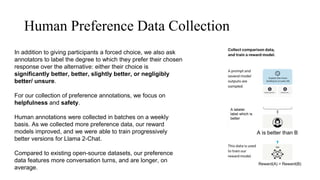
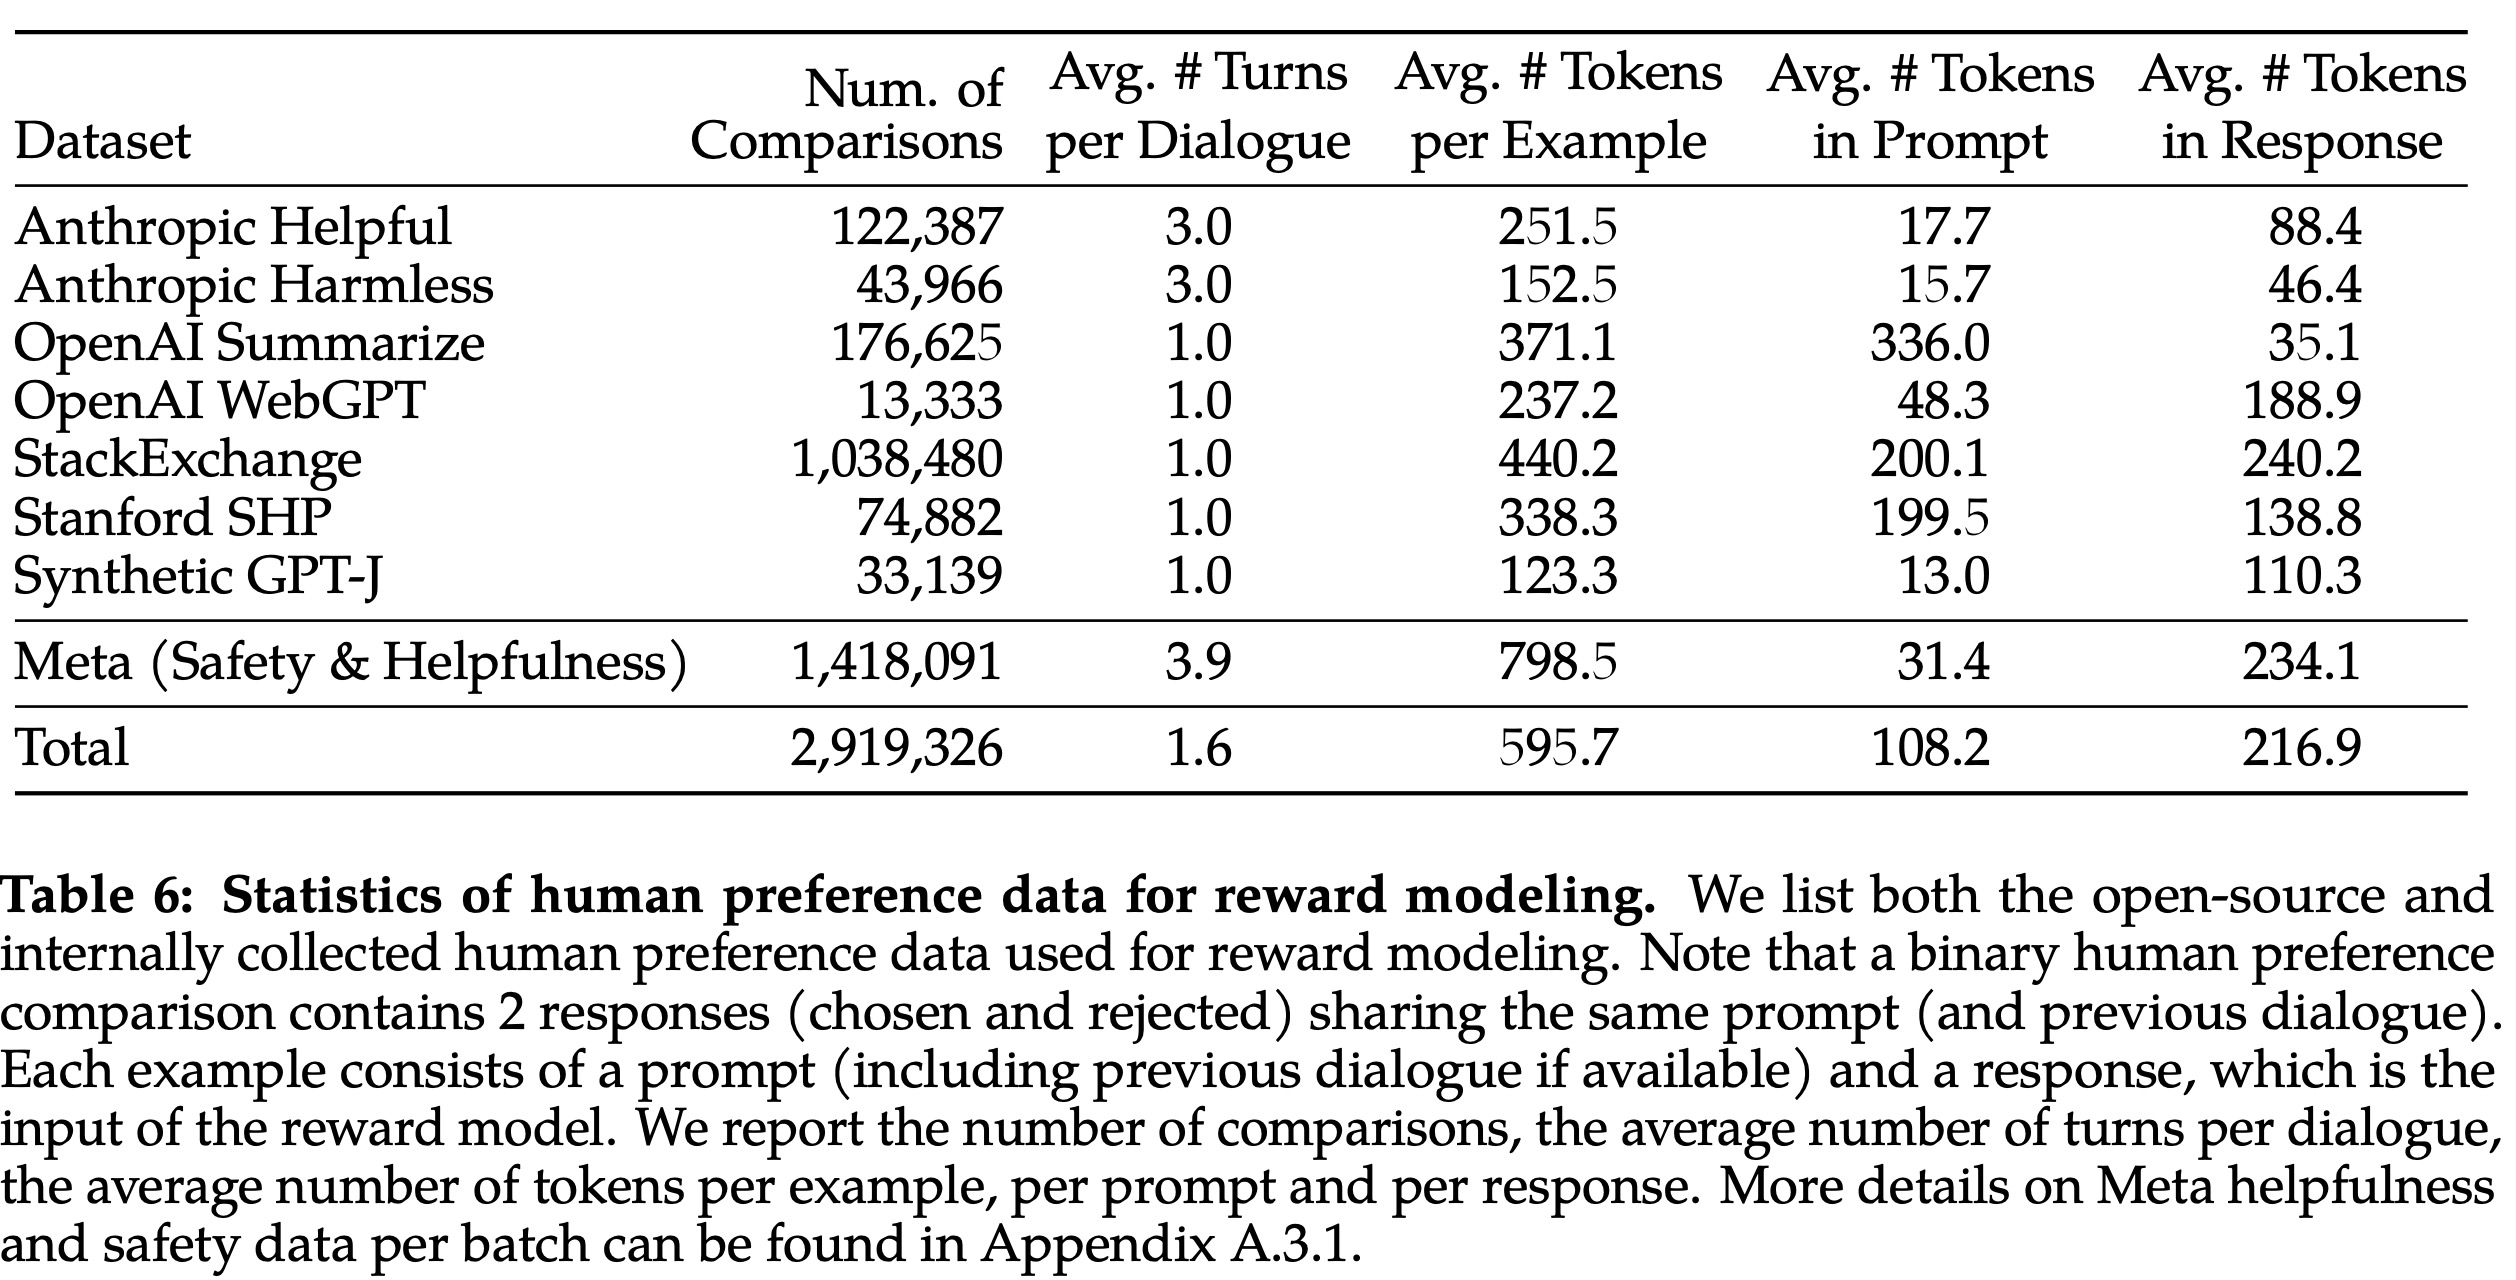
Llama 2: Open Foundation and Fine-tuned Chat Models | PPTX
The Story of RLHF: Origins, Motivations, Techniques, and Modern ...
When Slower Isn’t Truer: Inverse Scaling Law of Truthfulness in ...
Paper Review: Llama 2: Open Foundation and Fine-Tuned Chat Models ...
awesome-llm-human-preference-datasets by glgh - SourcePulse
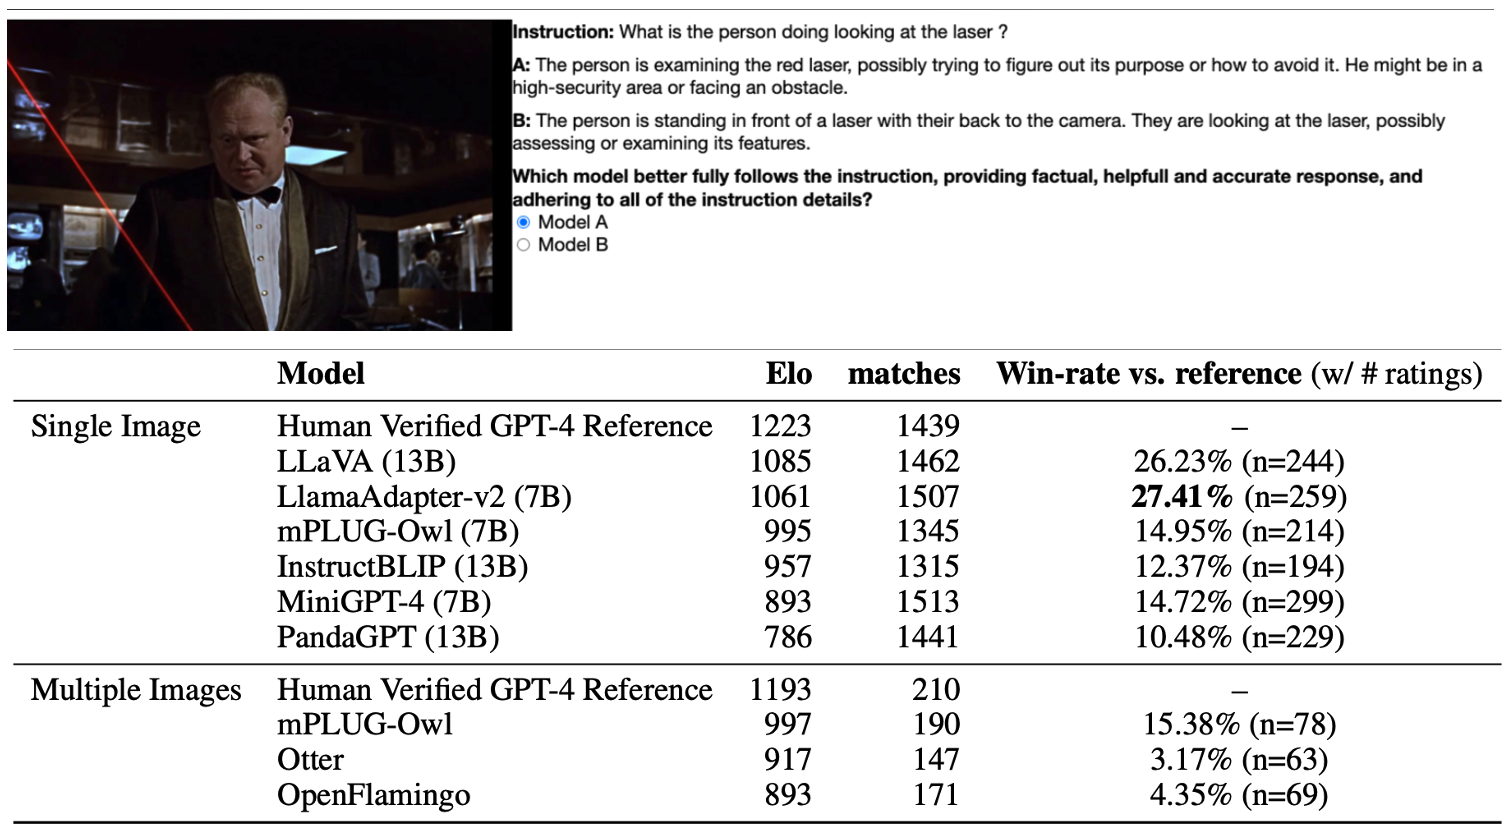
VisIT-Bench
Referring to Any Person · HF Daily Paper Reviews by AI
Llama 2 Open Foundation and Fine-Tuned Chat Models.pdf
datapointai/tts-human-preferences-large · Datasets at Hugging Face
Understanding and Using Supervised Fine-Tuning (SFT) for Language Models
Interpreting Language Model Preferences Through the Lens of Decision ...
Trinity-RFT: A General-Purpose and Unified Framework for Reinforcement ...
Do Explanations Generalize across Large Reasoning Models?
G-CLef @ CMU
Cross-lingual Human-Preference Alignment for Neural Machine Translation ...